A Regional AI Endpoint Does Not Settle Data Residency
One AI request can have different boundaries for inference, logs, abuse review, and support. The deployment setting and access controls matter more than the API hostname.
September 10, 2026 · 8 min read
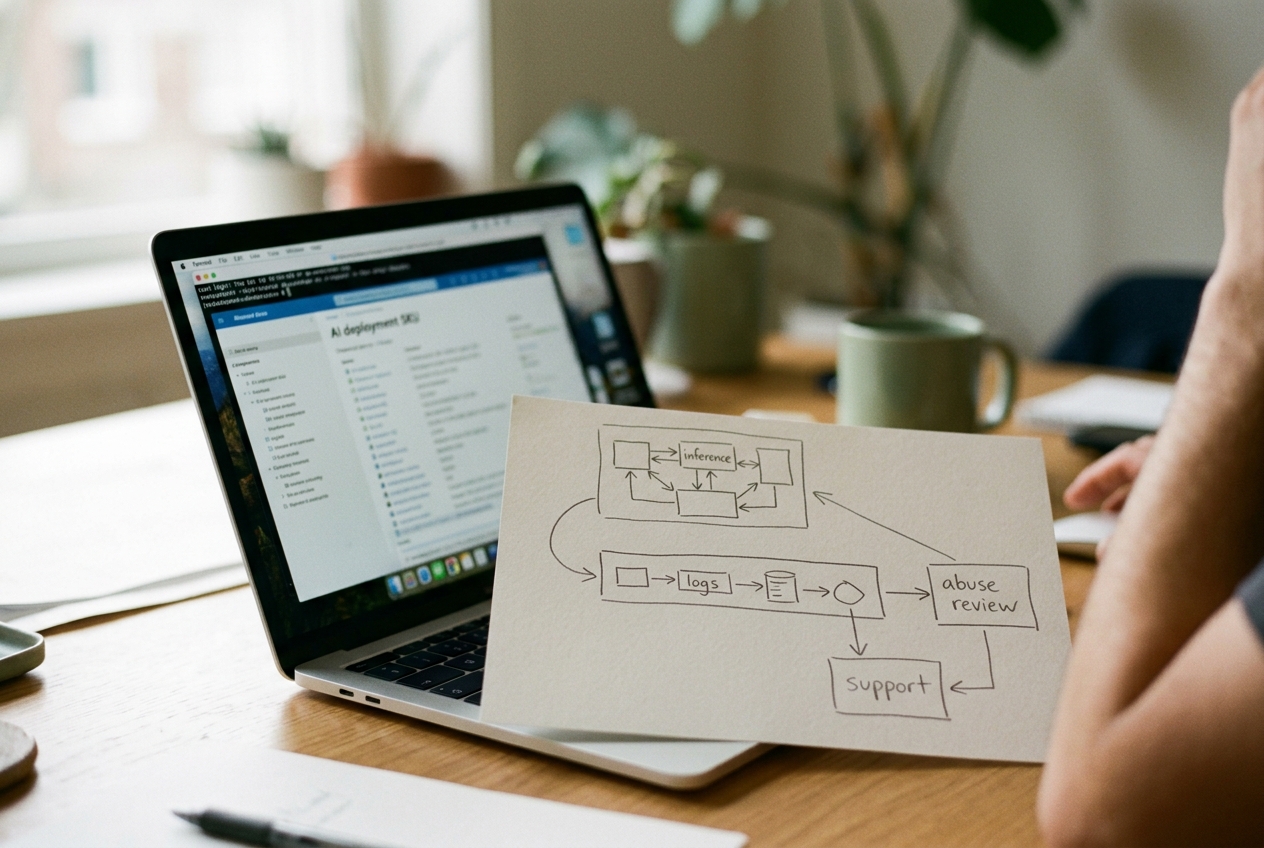
Take one architecture ticket: an insurer wants to send European claim notes to an Azure OpenAI resource created in Sweden Central, where a deployment named `claims-summary-eu` returns a short case summary. The policy attached to the ticket says claim text and generated summaries must remain in the European Union.
The endpoint passes a superficial check. It belongs to an Azure resource in Sweden Central, traffic uses TLS, and the deployment name includes “eu.” None of those details proves where the model runs, what content Microsoft may retain for abuse detection, or who could receive temporary access during a support case.
The decisive field is the deployment type. Microsoft documents separate scopes for Standard, Data Zone Standard, and Global Standard deployments: regional processing for Standard, processing within the selected US or EU data zone for Data Zone deployments, and potentially any Azure OpenAI geography where the model is available for Global deployments. The same resource endpoint can therefore front deployments with materially different processing boundaries.
That distinction makes a more useful review newly practical. Instead of approving “Azure OpenAI in Sweden,” the insurer can approve a named model deployment, deployment type, logging configuration, abuse-monitoring status, and support-access procedure as one versioned package.
Follow the request, not the hostname
An endpoint is the network address that accepts the API call. Inference is the computation that turns the submitted tokens into output tokens, and it may run behind that address in a different location allowed by the service configuration.
For `claims-summary-eu`, the first evidence should be the deployment record rather than a screenshot of the endpoint. If its SKU is `GlobalStandard`, Microsoft’s documentation says prompts and responses may be processed in any geography where the relevant Azure OpenAI model is deployed. Creating the resource in Sweden Central does not narrow that processing scope to Sweden or the EU.
Changing the deployment to `DataZoneStandard` would narrow inference to the EU data zone, where that option and model are available. A regional `Standard` deployment gives a more specific regional processing boundary, but the tradeoff can be lower quota, fewer available models, or less flexible capacity than the broader deployment types. Those constraints vary by model and region, so the approval record needs the actual deployment rather than a generic statement about Azure.
This is not unique to Microsoft. Amazon Bedrock separates regional API use from cross-region inference, a routing feature that sends a request from a source Region to one of the destination Regions listed for an inference profile. AWS publishes destination tables for geographic profiles, while global profiles can use a broader set of commercial Regions. Bedrock’s documentation also states that it does not store or log prompts and completions, does not use them to train AWS models, and does not share them with model providers.
The comparison matters. Bedrock can offer a relatively restrictive content-retention position while still routing inference across Regions when a cross-region profile is selected. Azure can keep processing within an EU data zone while retaining selected content for its standard abuse-monitoring workflow. “Regional,” “no training,” and “no prompt storage” describe different controls.
For the claim-summary ticket, request written answers to four points: the source region, every permitted inference region, the behavior during capacity pressure, and whether failover can widen the boundary. A vendor’s published destination table is stronger evidence than a hostname; a contractual commitment is stronger than an architecture diagram that carries no service terms.
Logging creates a second copy
After inference, trace every place the claim notes or generated summary could be written. Start with the vendor service, then inspect the insurer’s API gateway, application telemetry, error tracker, and developer console, because a compliant model deployment can still feed full prompts into an unrestricted log sink.
Microsoft says Azure OpenAI prompts and completions are not made available to OpenAI and are not used to train Microsoft or third-party foundation models without permission. Its standard abuse-monitoring system is a separate matter: automated systems inspect content, and prompts or completions associated with suspected abuse may be stored for up to 30 days and reviewed by authorized Microsoft employees.
That documented 30-day window belongs in the data-flow diagram as another storage path. The review should identify the storage geography, encryption and separation controls, deletion schedule, reviewer authorization, and evidence available after deletion. “Not used for training” answers none of those points.
Microsoft also documents a modified abuse-monitoring program for eligible managed customers. An approved customer can avoid storage and human review of prompts and completions for abuse monitoring, although automated abuse detection still applies. Eligibility and approval are not inherited from an enterprise agreement, and a pending application should not be represented as an active control.
Now return to `claims-summary-eu`. Even if that deployment receives modified abuse monitoring, an API gateway policy that records request and response bodies may preserve every claim indefinitely in a general-purpose logging account. Debug traces can do the same when an engineer enables verbose logging for one failed call and forgets to remove it.
The practical setup step is to send a synthetic claim containing a unique marker through the complete production path, then search each approved telemetry store for that marker. This does not prove the absence of undisclosed vendor copies, but it verifies whether the systems the team controls are duplicating content. Repeat the test after gateway, software development kit, or observability changes.
Human access has its own boundary
Data residency policies often describe storage and processing locations but say little about where an authorized reviewer may sit. Abuse review and support access therefore need separate decisions, even if both use tightly controlled accounts.
For abuse monitoring, ask whether a human can see the full prompt and response, a redacted excerpt, or only classifier metadata. Record the conditions that trigger review, the maximum retention period, the locations from which reviewers may connect, and whether customer notification or an audit record exists. If documentation promises authorized personnel without defining their location, the review has found an unresolved point rather than an EU-only control.
Support works differently. A routine ticket containing an error code need not include claim text, but troubleshooting may lead an engineer to request request IDs, diagnostic bundles, or temporary resource access. Azure Customer Lockbox is designed to let customers approve or reject certain Microsoft support access requests; relying on it requires checking that the subscription, service, and requested operation are covered, then preserving the approval record.
The insurer should adopt a support runbook before production. First-line tickets include deployment identifiers, timestamps, token counts, and sanitized errors, not prompt bodies. Engineers reproduce faults with synthetic claims. Any request for access to customer content moves to a named approver, receives a time limit, and produces an auditable record under the organization’s existing incident process.
That runbook costs some troubleshooting speed. A production-only formatting failure may take longer to reproduce after personal and medical details are removed, while refusing all vendor access can leave rare service faults unresolved. The fallback is controlled, time-bound access, not an engineer pasting the original claim into a support portal whose residency has never been assessed.
Turn documentation into deployment evidence
A workable approval for `claims-summary-eu` fits into four records. The deployment export proves its model, region, and SKU. The vendor documentation or contract defines permitted inference locations. The logging configuration and marker test show which customer-controlled systems copy content.
Abuse-monitoring and support records establish retention and human-access conditions.
Capture those records in the same change process used for production infrastructure. A model upgrade can force a new deployment type; a quota change can push traffic toward Global Standard; an engineer can replace a regional Bedrock call with a cross-region inference profile to reduce throttling. Each change may improve availability while invalidating the original residency conclusion.
The review should also distinguish a documented guarantee from an observed result. Network traces can show the address contacted and latency can suggest distance, but neither proves where inference occurred inside a managed service. Cloud account configuration, vendor documentation, destination tables, contractual terms, and access logs provide the evidence that an auditor can evaluate.
For this insurer, the endpoint remains useful evidence that the application called the intended Azure resource. It is one line in the file. The approval turns on the `claims-summary-eu` deployment SKU, the abuse-monitoring status, the absence of prompt bodies in gateway logs, and the support-access record attached to that exact production configuration.
Questions people ask
Does an
EU AI endpoint guarantee that inference stays in the EU?
No. The deployment or routing mode sets the processing boundary. Azure Global Standard can process requests across available geographies, while an EU Data Zone deployment narrows processing to the EU data zone. Check the named deployment type and model availability rather than inferring residency from the resource location or URL.
Is
“not used for training” the same as zero data retention?
No. Training, service logging, and abuse monitoring are separate uses. A vendor may promise not to train on customer prompts while retaining selected prompts and outputs for a documented abuse-review period. Confirm what is stored, for how long, in which geography, and whether a human reviewer can access it.
Can application logging break an otherwise compliant setup?
Yes. API gateways, error trackers, tracing tools, and debug consoles can copy full prompts or responses into storage with a different region and retention policy. Send a synthetic request containing a unique marker, search every approved telemetry destination, and remove or redact body logging before processing regulated data.
What should a data-residency approval name?
Name the provider, model, deployment identifier, deployment or inference-profile type, permitted processing regions, content-retention setting, abuse-review status, and support-access procedure. Attach configuration exports and the relevant vendor documentation. If the deployment type or routing profile changes, rerun the review before the claim-summary workflow returns to production.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.