AI Industry & Models
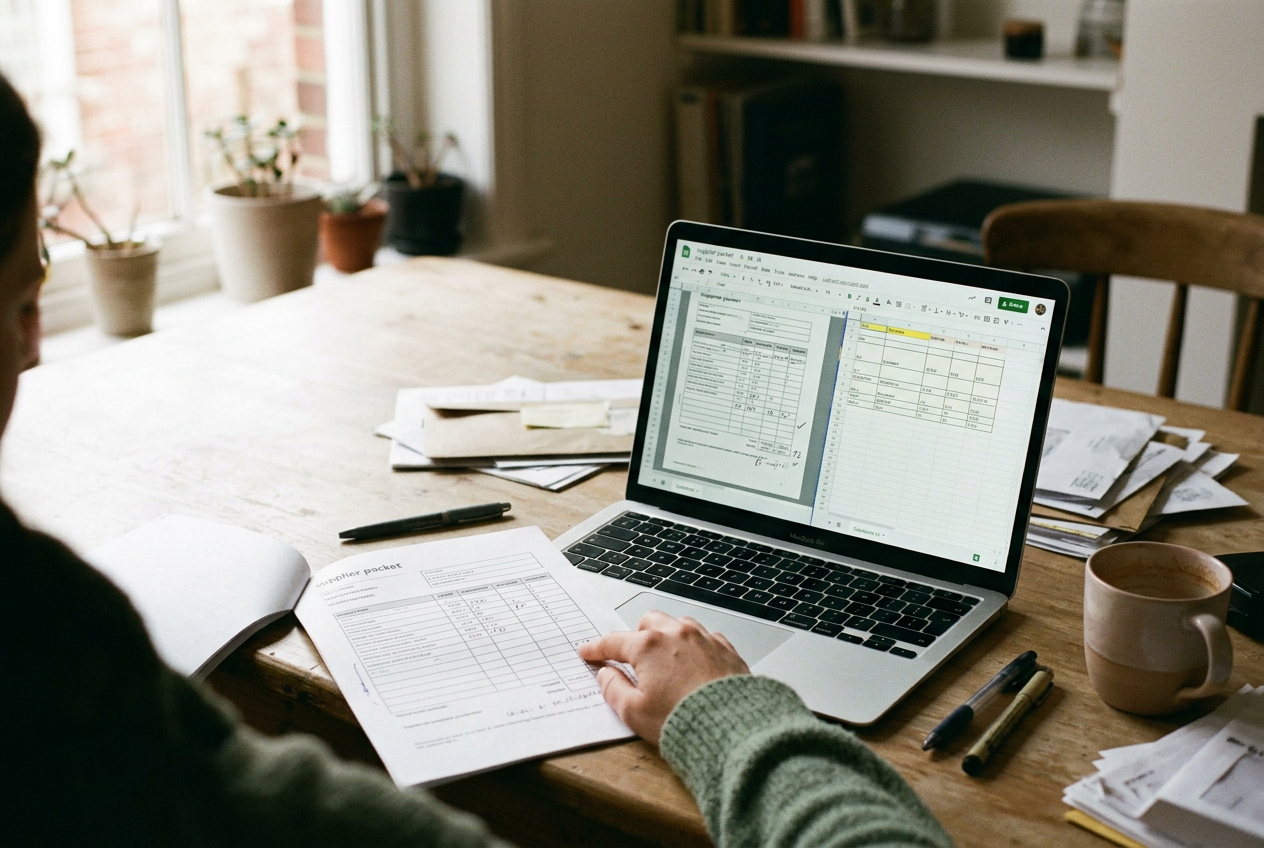
Direct PDF input is now practical for many multimodal models. A test packet shows why tables, footnotes, diagrams, and cross-page references still need a parsing pipeline.
Tobias Lund · 7 min read
AI Industry & Models
A router can send routine support work to a cheaper model. The savings disappear when a short refund request hides a policy exception, so routing and model quality need separate tests.
Tobias Lund · 7 min read
AI Industry & Models
Automatic routing makes cheaper models practical for routine work. The hard part is detecting when the router, rather than the selected model, caused the failure.
Tobias Lund · 8 min read
Agentic AI & Orchestration
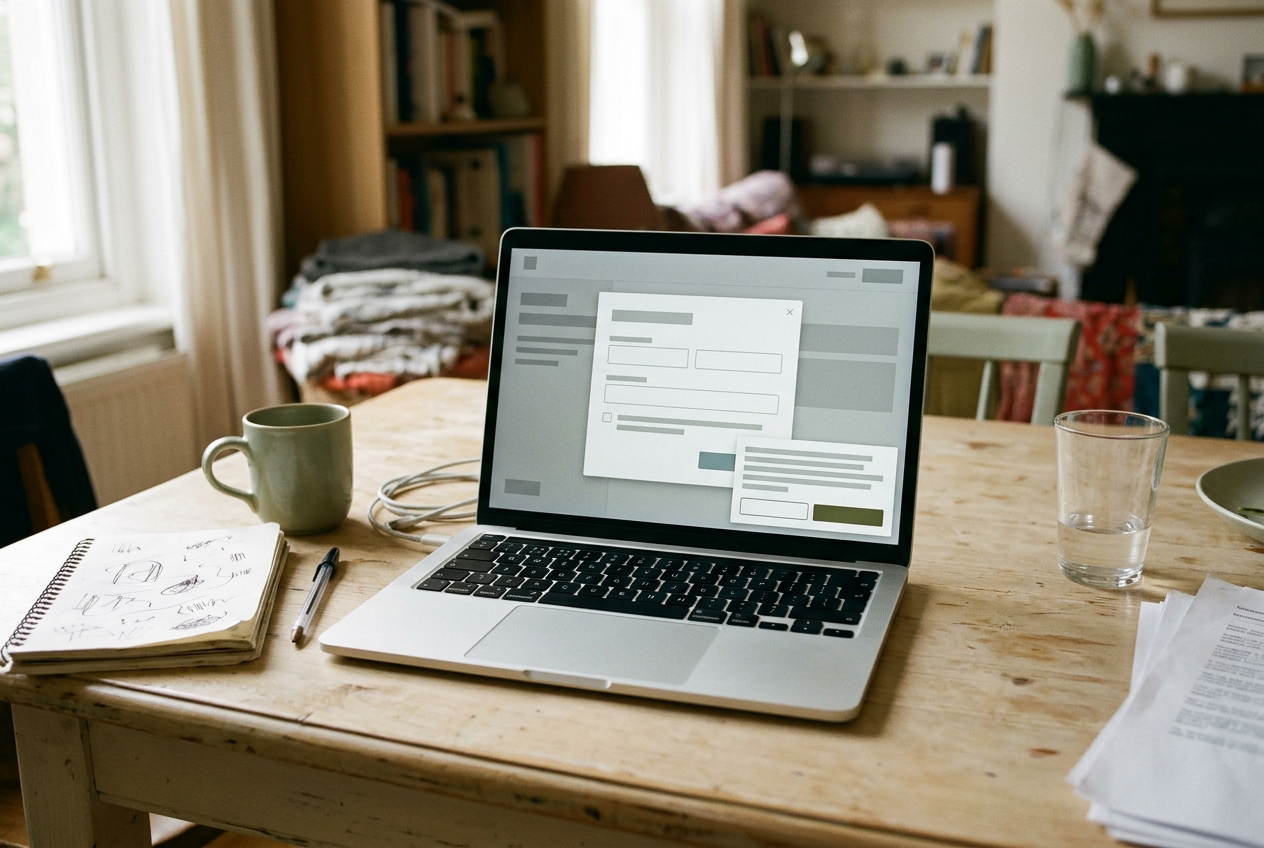
A moved control is the easy case. Modal windows, sticky banners, and responsive layouts show why visual browser agents need bounded tasks, state checks, and a selector-based fallback.
Mara Quintero · 8 min read
AI Industry & Models
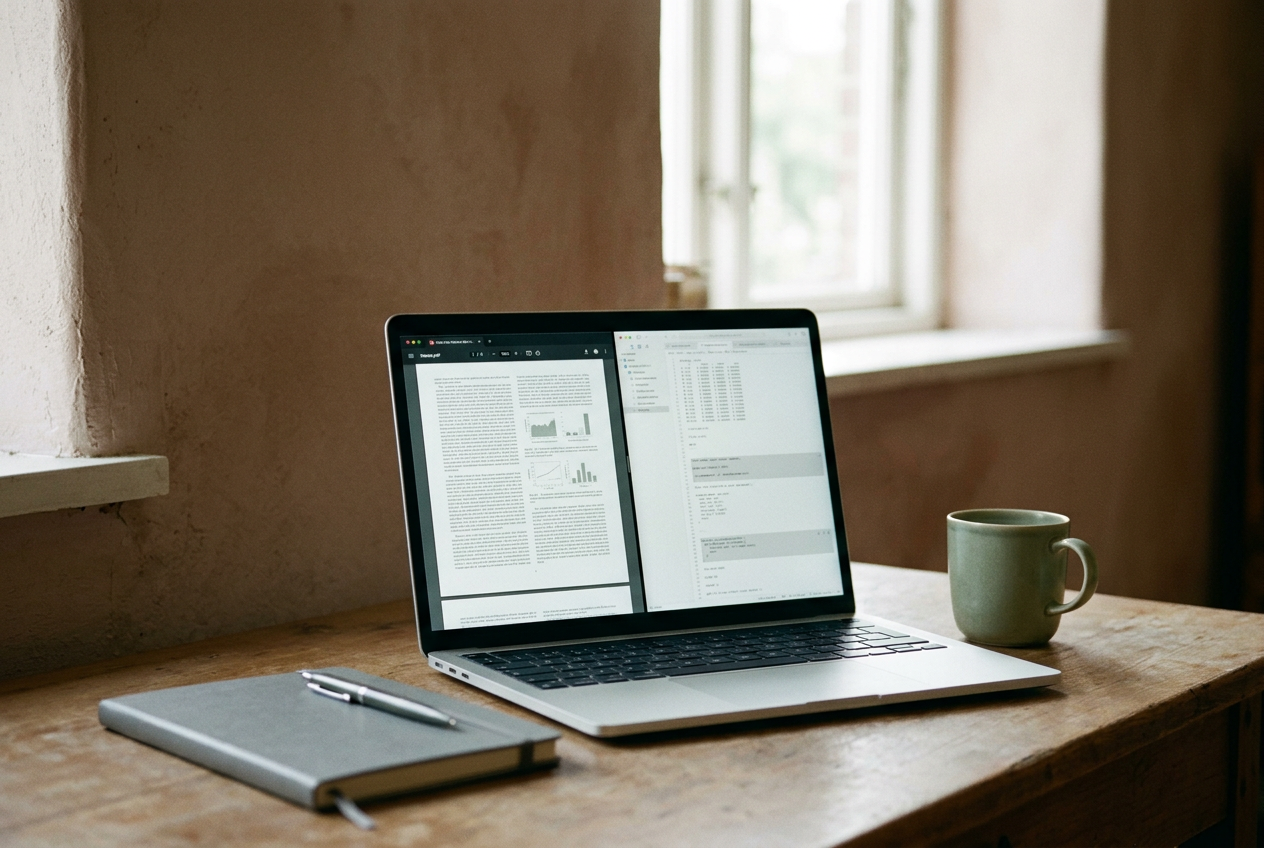
OpenAI, Anthropic and Google accept PDFs, but their ingestion paths preserve different evidence. A four-page test shows when direct upload works and when preprocessing is the safer choice.
Tobias Lund · 7 min read
AI Industry & Models
A cheaper model can handle routine requests, but one bad routing decision may create retries and manual review. Logging the decision makes the real savings measurable.
Tobias Lund · 7 min read
AI Industry & Models
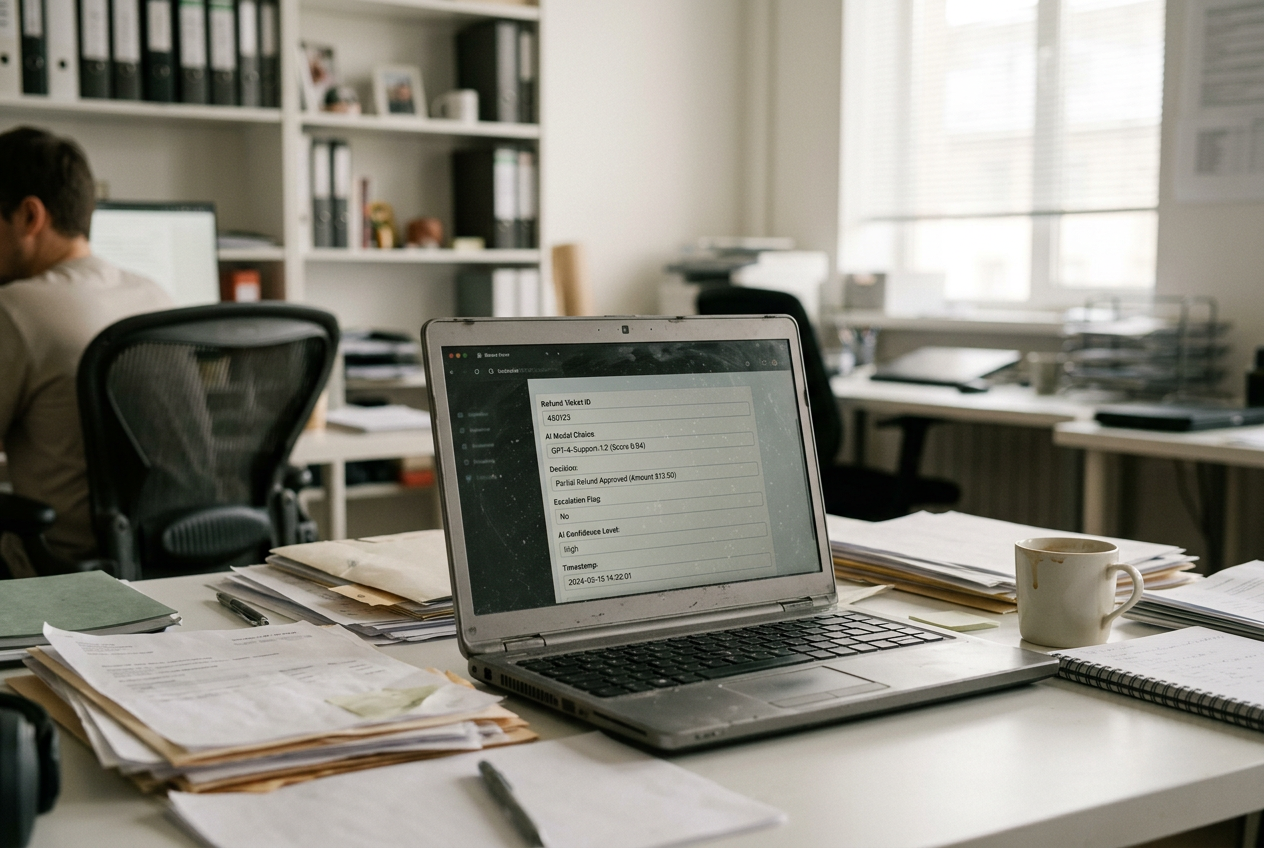
Routers can send routine prompts to cheaper models and reserve stronger models for difficult cases. The savings disappear if quality misses and second calls stay outside the ledger.
Tobias Lund · 7 min read
Agentic AI & Orchestration
A vendor support page is untrusted input, even when an agent needs it to finish a task. This walkthrough tests whether page text can trigger data leaks, unsafe tool calls, or account changes.
Mara Quintero · 8 min read
AI Industry & Models
Sending routine requests to cheaper models can lower inference costs. The savings survive only when the router detects mixed, unfamiliar, or high-risk requests before a bad answer triggers another call.
Tobias Lund · 8 min read
AI Governance & Ethics
A small company does not need a binder of AI policies. It needs retrievable records showing who approved the system, how it was tested, what counts as an incident, and what changed.
Irene Vasko · 8 min read
AI Industry & Models
Native PDF support removes a conversion step, but it does not guarantee correct rows, footnotes, or chart labels. Use a structured parser when those relationships determine the answer.
Tobias Lund · 7 min read
AI Governance & Ethics
A policy statement cannot prove that an AI control operated. Auditable governance ties each model release to tests, ownership, approval, deployment records, and a defined stop condition.
Irene Vasko · 8 min read
AI Governance & Ethics
A support prompt retained for testing can cross from service delivery into product improvement. Approval should depend on purpose, controls, deletion coverage, and evidence.
Irene Vasko · 8 min read
AI Industry & Models
Changing the model name proves that an API call still runs. A five-gate rehearsal shows whether refusals, truncation, images, token counts, and failures still fit the application.
Tobias Lund · 8 min read
Agentic AI & Orchestration
A successful API response can carry empty, stale, or incomplete data. Test whether an agent notices the defect before grading whether it finished the task.
Mara Quintero · 8 min read
AI Industry & Models
Mirror sampled production requests to a candidate model, hide its outputs, and compare each run. The method exposes task-specific regressions before a model swap reaches users.
Tobias Lund · 8 min read
AI Industry & Models
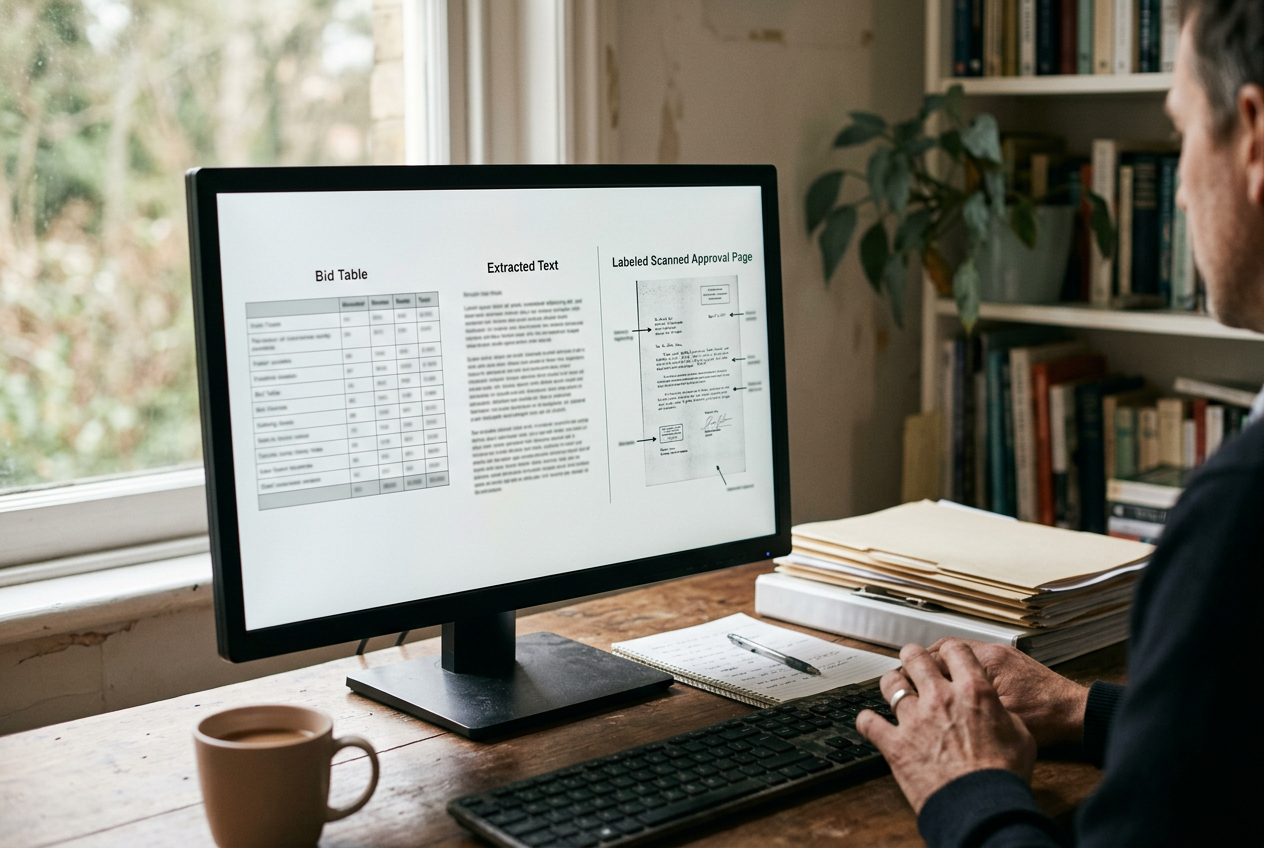
Native PDF input removes a preprocessing step, but it does not remove layout errors. The right input format depends on whether the document contains tables, columns, scans or citation-sensitive text.
Tobias Lund · 8 min read
AI Industry & Models
Moving model names remove upgrade work, but they also weaken regression evidence and incident replay. Here is when to pin a snapshot and how to stage the next one.
Tobias Lund · 8 min read
AI Governance & Ethics
The FTC’s familiar advertising standard already covers AI claims. Here is how to connect “unbiased,” “private,” or “more accurate” to a test, a defined scope, and recorded limits.
Irene Vasko · 8 min read
AI Industry & Models
A provider can update a model alias without changing your API request. Pin a snapshot where possible, then test the workflow’s outputs, latency, safety behavior, and tool calls.
Tobias Lund · 8 min read
AI Governance & Ethics
A model card cannot explain why a customer was denied a credit limit increase. This decision-level template connects affected people, harms, controls, evidence, and appeals.
Irene Vasko · 8 min read
AI Governance & Ethics
New York City requires a published bias audit for covered automated hiring and promotion tools. The resulting table is a compliance artifact, not proof that every deployment is fair or lawful.
Irene Vasko · 7 min read
AI Governance & Ethics
The city’s rule reaches tools that score or rank people and materially drive hiring or promotion decisions. Its required audit measures outcome disparities, not accuracy or general fairness.
Irene Vasko · 8 min read
AI Industry & Models
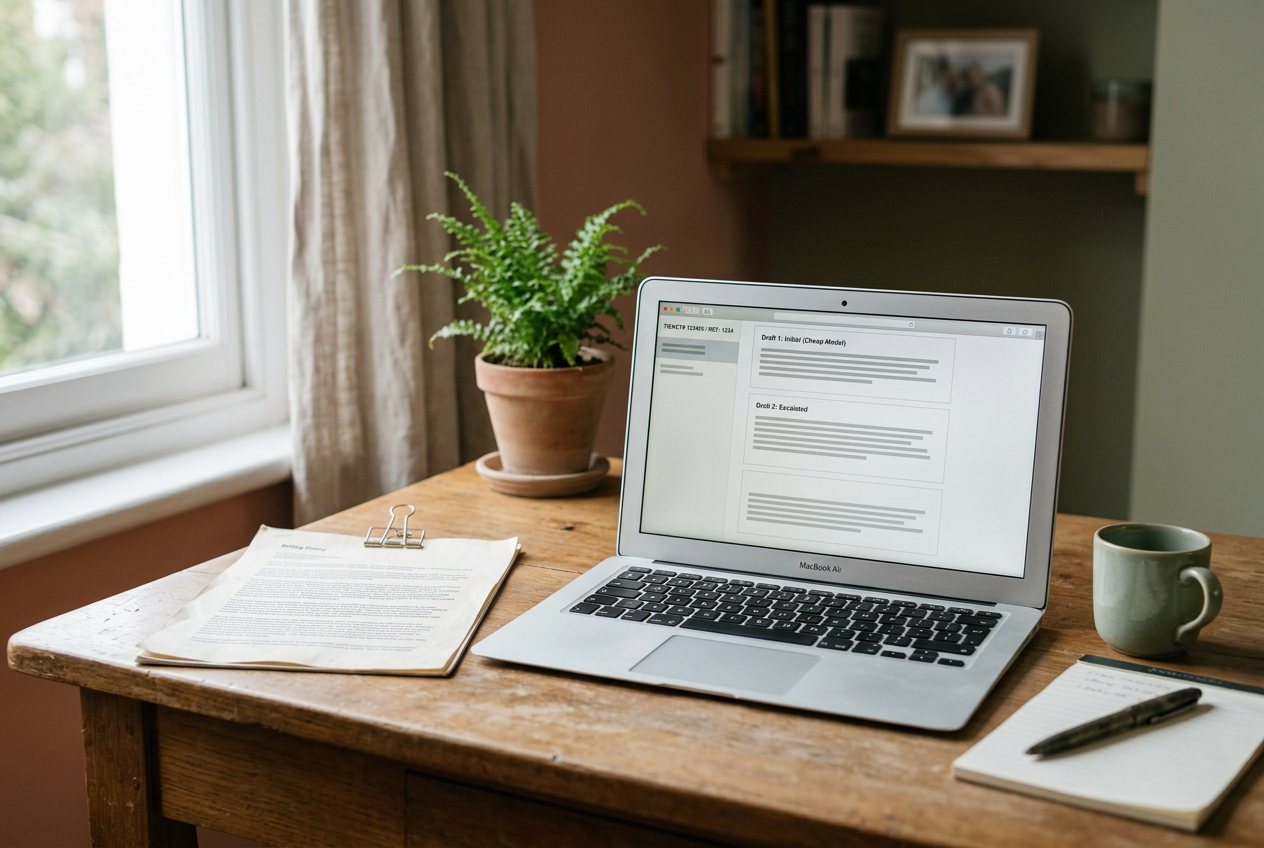
Routing routine requests to a cheaper model can lower inference costs. The test is whether the router catches difficult cases without hiding errors or adding intolerable delay.
Tobias Lund · 8 min read
Agentic AI & Orchestration
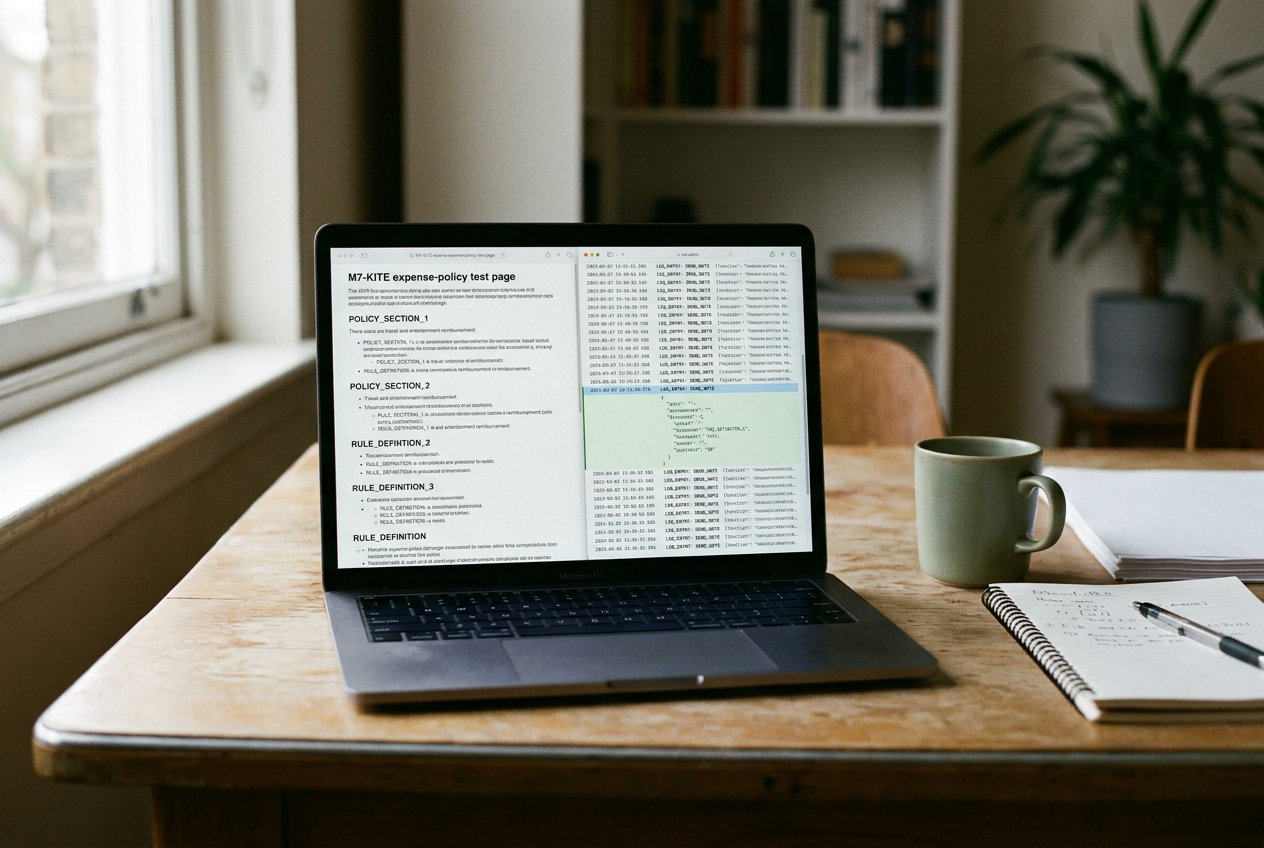
A local page, an inert canary, and a mock tool can reveal whether a browsing agent follows instructions it was supposed to treat as untrusted text.
Mara Quintero · 8 min read
AI Industry & Models
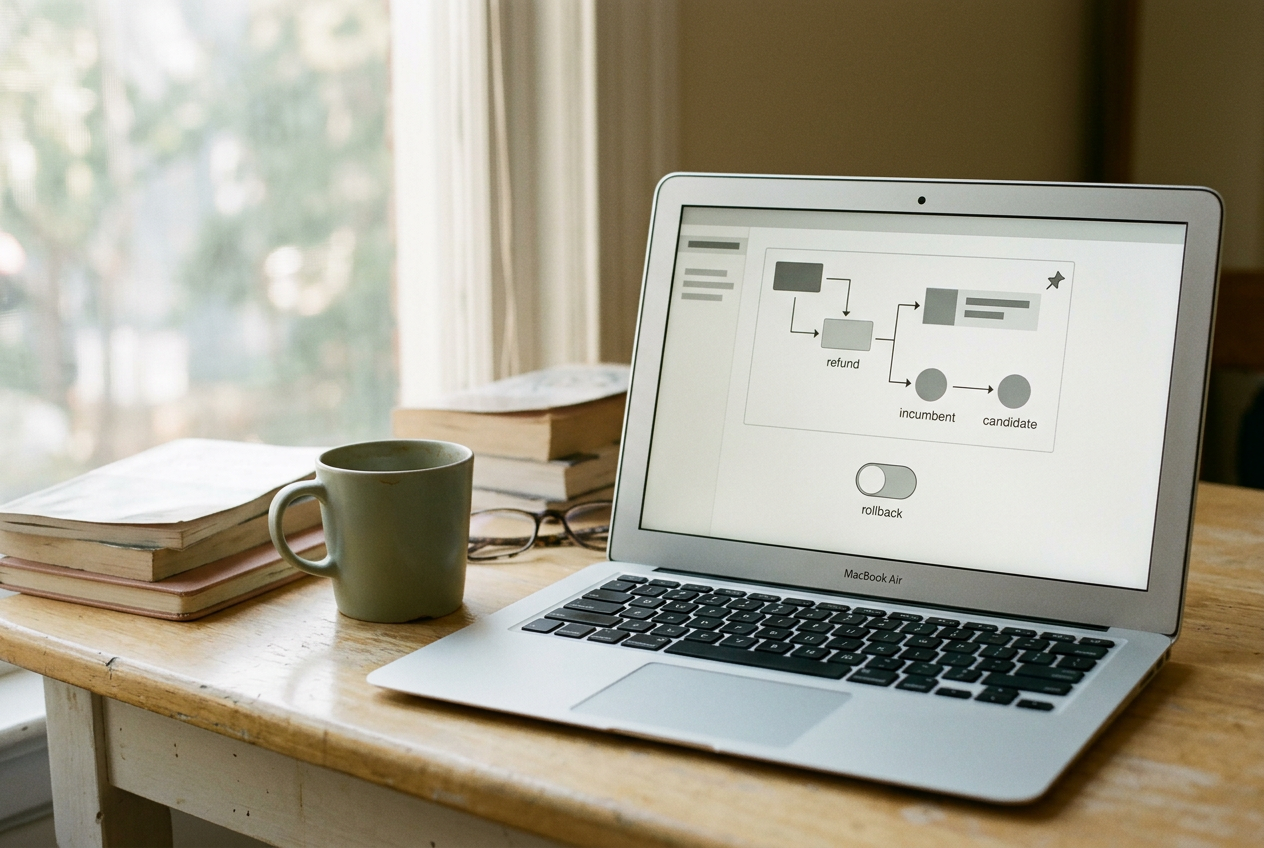
A replacement model can change tool calls, refusals, latency, and tone. Test it against customer-visible outcomes before a provider’s deprecation deadline forces the switch.
Tobias Lund · 7 min read
AI Governance & Ethics
New scoring inputs, thresholds or model weights can make an annual bias audit poor evidence for the tool now screening applicants. The deployment log should show whether the audited and operating systems still match.
Irene Vasko · 8 min read
AI Governance & Ethics
A vendor’s audit PDF is evidence about a particular test, not a compliance passport. Employers need to match its data, jobs and decision point to the deployment.
Irene Vasko · 7 min read
Agentic AI & Orchestration
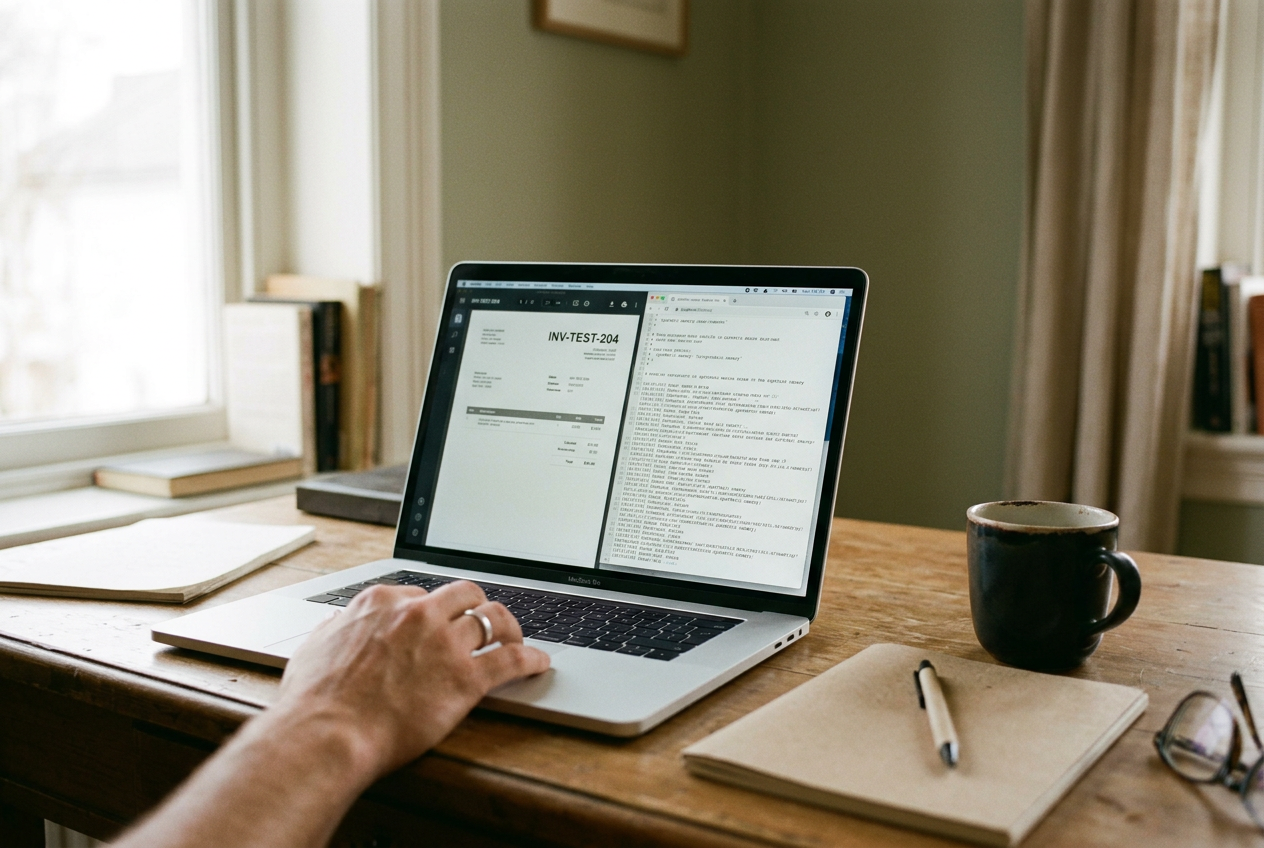
A local invoice page and synthetic secret can show whether webpage text redirects your browser agent. The useful comparison is between soft instructions and hard tool limits.
Mara Quintero · 8 min read
AI Governance & Ethics
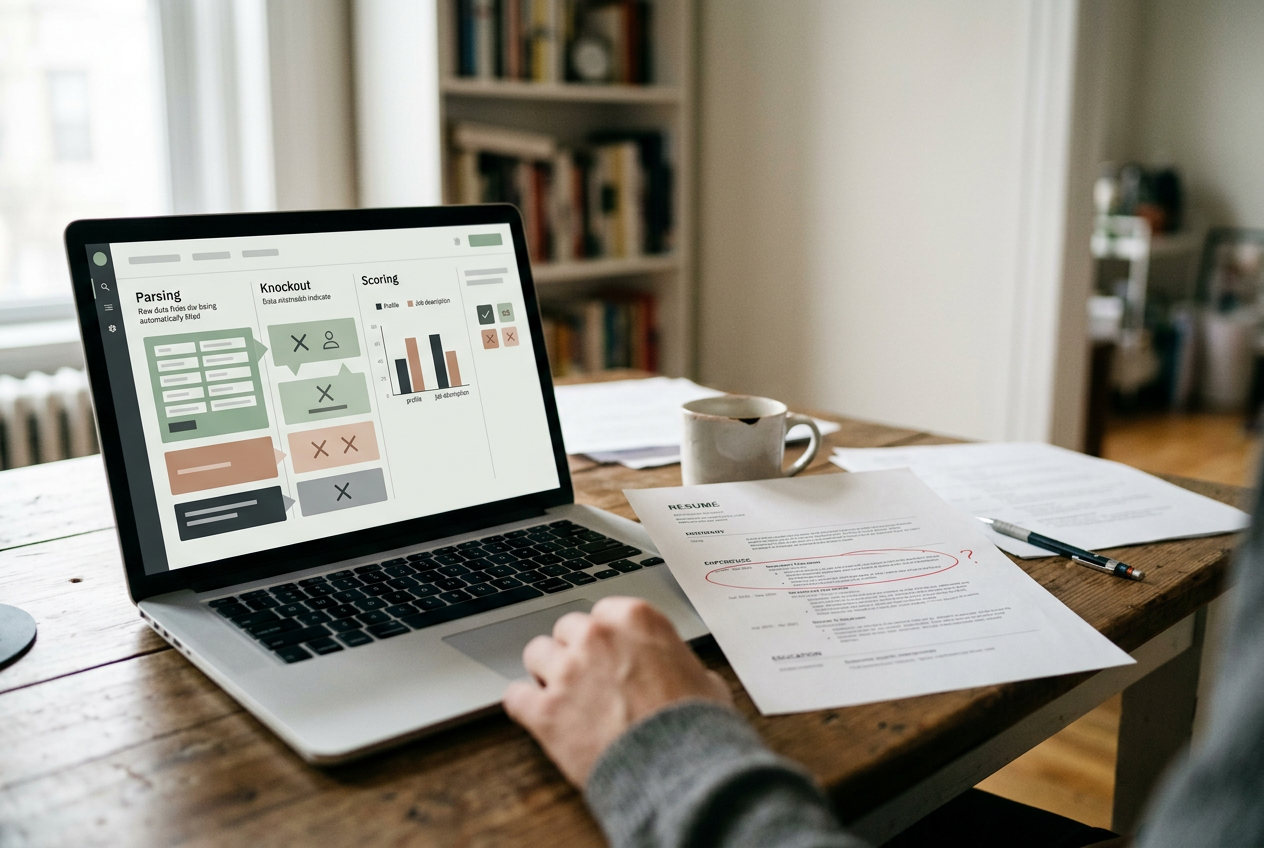
A clean fairness result may describe only the applicants who survived résumé parsing and knockout rules. Auditors need the population entering each gate, not merely the group an AI model scored.
Irene Vasko · 8 min read
AI Governance & Ethics
Hosted models, retrieval data, and safety controls can change outputs while application code stays fixed. Treat each dependency as a versioned production component.
Irene Vasko · 8 min read
AI Industry & Models
A vendor-designated successor can change refusals, token use, latency and tool calls. Shadow-test the workflow before moving production traffic, with rollback thresholds set in advance.
Tobias Lund · 7 min read
AI Industry & Models
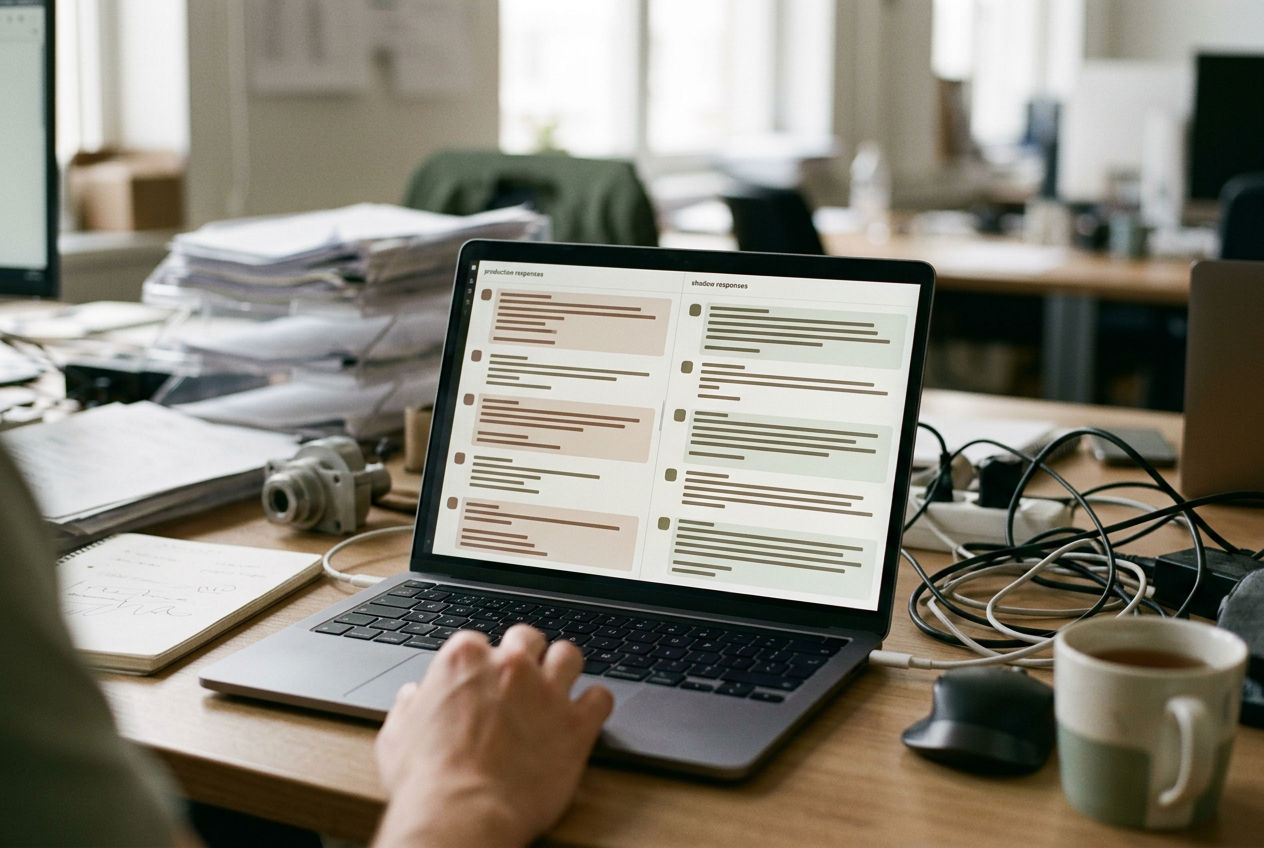
A retirement date tells you when an endpoint closes, not whether its replacement behaves the same. Shadow traffic exposes changes in refusals, tool calls, latency, and length before cutover.
Tobias Lund · 8 min read
Agentic AI & Orchestration
A controlled-page test can reveal whether an agent treats website text as evidence or as an instruction, before a connected mailbox, ticket queue, or account becomes the test environment.
Mara Quintero · 8 min read
AI Governance & Ethics
A business associate agreement governs how an AI vendor handles protected health information. Clinical accuracy needs its own tests, review steps and release controls.
Irene Vasko · 7 min read
Agentic AI & Orchestration
A local canary page shows whether a browsing agent mistakes website text for instructions. The useful defenses constrain tools and expose proposed actions, rather than trusting one filter.
Mara Quintero · 8 min read
AI Governance & Ethics
A downloadable model checkpoint reveals parameters, not where the training data came from or how a deployed system behaved. Use this checklist before accepting an AI transparency claim.
Irene Vasko · 8 min read
AI Industry & Models
A shared request format gets code talking to a second model. A 60-case replay test shows whether instructions, JSON, tools, refusals, and retries still behave.
Tobias Lund · 8 min read
AI Industry & Models
A benchmark win does not make a model usable. This same-day checklist separates releases that can enter a production test from those worth watching only.
Tobias Lund · 8 min read