Model Routing Cuts Cost Only When Wrong Routes Are Counted
Routers can send routine prompts to cheaper models and reserve stronger models for difficult cases. The savings disappear if quality misses and second calls stay outside the ledger.
September 22, 2026 · 7 min read
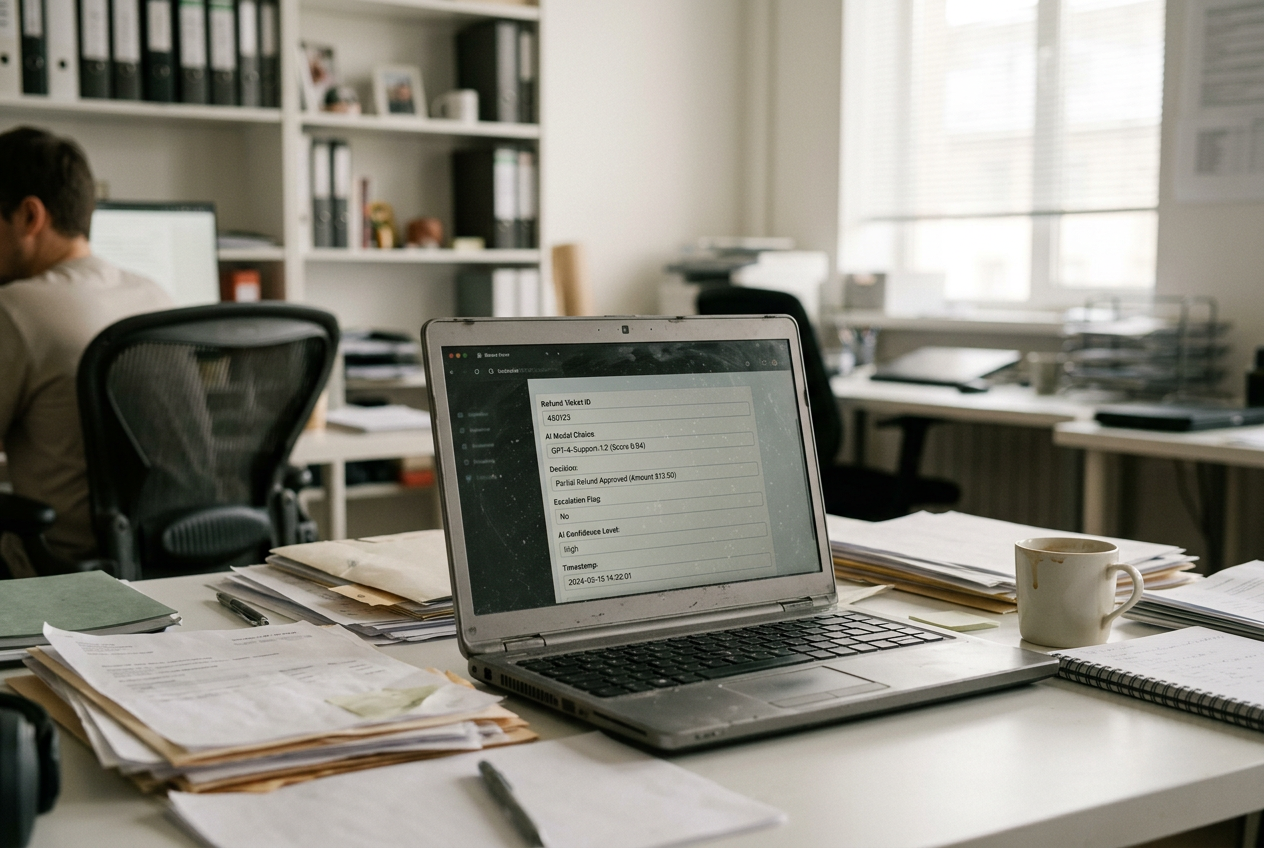
Consider one support ticket asking whether an order qualifies for a refund. The application can send a routine request with a clear purchase date to a low-cost model, while a ticket involving a policy exception, contradictory account notes or missing order data goes to a stronger model.
That split is newly practical because routing has moved from custom application logic into managed services and open-source tooling. In December 2024, Amazon Bedrock introduced intelligent prompt routing, which its documentation says selects between models in the same family based on predicted response quality. AWS advertises cost reductions of up to 30% while maintaining quality, a vendor result rather than an independent guarantee. OpenRouter also documents an Auto Router that chooses a model from a supported pool, while the 2024 RouteLLM project showed how teams can train a router from preference data.
The mechanism is straightforward. A router, meaning a classifier that chooses which model receives a request, inspects the support ticket and predicts whether the cheaper model can answer it. That decision may cost far less than generating the answer, but it creates a new failure point: the router can classify a difficult refund case as easy, produce a fluent wrong answer and never trigger the expensive model.
A lower invoice proves little unless that mistake appears in the evaluation.
Label the decision the router should have made
Start with a fixed test set of real, redacted support tickets and send every ticket to both candidate models. Score each output against the same rubric: whether it identifies the applicable policy, uses the correct order facts, avoids unsupported claims and takes the permitted action. A human reviewer or a separately validated model judge can apply the rubric, though model-based grading needs periodic human checks because a judge can share the answer model’s blind spots.
The useful label is the cheapest model that passes the rubric. Evaluation teams sometimes call this an oracle route: the best routing decision known after all candidate outputs have been inspected. If the cheap model passes, its ticket receives a “cheap acceptable” label even when the stronger model writes a more polished reply. If only the stronger model passes, the correct label is “strong required.
” When neither passes, the router has no correct model to choose; the prompt, retrieval step or underlying workflow needs repair.
That produces four measurable outcomes. A correct cheap route saves money without crossing the quality threshold. A correct strong route protects quality. A false expensive route wastes money by sending an easy ticket to the stronger model.
A false cheap route is the dangerous one because the system returns an unacceptable answer while reporting a successful low-cost call.
The two errors should not carry equal weight. For the refund workflow, a false expensive route adds model spend and perhaps latency, while a false cheap route can misstate policy or authorize an action the support system should reject. Set separate limits for each error rather than collapsing both into one routing-accuracy percentage.
Keep the label beside the production decision. The support-ticket log should record a request identifier, the router’s chosen model, its confidence or score, the oracle route when available, the rubric result, input and output token counts, latency, escalation reason and final model used. Without the oracle label, the log shows what happened but cannot show whether the route was correct.
Observe the answer the router hid
A router prevents teams from seeing the main counterfactual: what the other model would have returned. If production sends the refund ticket only to the cheap model, a normal pass-or-fail review can detect a bad answer, but it cannot determine whether the stronger model would have fixed it. The reverse matters too. Sending a ticket to the costly model does not prove that the cheaper one would have failed.
During initial evaluation, run every test prompt through both models. After launch, use shadow evaluation, where a sampled request also runs against an alternative model without exposing that second answer to the user. The shadow call costs money, so the sample can shrink once error rates stabilize, but it should remain large enough to include the difficult ticket categories the router rarely sees.
Sampling only random traffic can miss those categories. Stratify the evaluation by documented prompt classes such as routine status checks, refund eligibility, policy exceptions and requests requiring account tools, then report false-cheap rates for each class. A router that looks acceptable across all traffic may still mishandle most policy exceptions if routine questions dominate volume.
Routing confidence also needs calibration. A score of 0.8 should correspond to a known likelihood that the selected cheap model will pass; otherwise, the number is merely useful for ranking. Plot pass rates by score band, choose the escalation threshold from observed results and rerun that calibration after changing either model, the system prompt, retrieval data or available tools.
Return to the refund ticket after each change. A stronger cheap model may turn yesterday’s “strong required” examples into safe low-cost routes, while a revised policy document can make old evaluation labels obsolete even though neither model changed.
Price the whole escalation path
The cheapest first call is not necessarily the cheapest completed ticket. Calculate cost from the full path:
`route cost = router cost + first model call + retrieval or tool charges + retry calls + escalation call`
For token-priced APIs, calculate each model call from its input tokens multiplied by the published input rate, plus output tokens multiplied by the output rate. Record the price sheet and date used because vendors change rates, discounts and caching terms. If a provider bills cached input, batch processing or tools differently, those charges belong in the same calculation.
There are two common escalation designs. A pre-generation router sends the refund ticket directly to one model, which avoids paying for a discarded cheap answer but depends heavily on classification quality. A generate-then-check design lets the cheap model answer first and escalates when a verifier rejects that answer; it may catch more failures, yet each rejected ticket pays for the cheap generation, the verification step and the stronger generation.
Some applications run two models in parallel and choose between their answers. That can reduce the latency of an escalation because both outputs arrive around the same time, but it pays for both on every routed request. For cost reduction, parallel generation is usually the wrong default unless the workflow values response time more than inference spend.
Price these branches separately. Report the share sent directly to the cheap model, the share sent directly to the strong model and the share that paid for more than one generation. Then calculate cost per accepted answer, not cost per API call. A failed cheap response followed by a successful strong response is one completed support ticket with two generation bills.
Latency needs the same treatment. Compare median and tail latency for completed requests, including retries and tool calls, rather than quoting the cheap model’s isolated response time. A routing classifier may add little delay, while a sequential escalation can make the hardest tickets wait through two full generations.
Keep one model as the control
The baseline should be deliberately boring: send every ticket to the stronger model using the same system prompt, retrieved documents, tools, output format and acceptance rubric. Measure its total cost, pass rate and completed-request latency on exactly the same ticket set used for the router.
This control answers the adoption question. A router is useful when it lowers cost per accepted answer while keeping false-cheap errors within the workflow’s limit. If it cuts raw model spend but lowers the acceptance rate, its apparent savings include work transferred to human agents, retries or customer corrections. Add those downstream events where they can be measured; otherwise, report them separately rather than assigning invented dollar values.
Do not compare a routed system against an older prompt or a weaker baseline configuration. The routing layer gets credit only for the difference created by model selection. Retrieval improvements, prompt rewrites and new tools should be tested independently or applied to both sides.
Run the comparison again whenever a model alias changes, a vendor retires a version or the prompt distribution moves. Managed routing reduces the engineering needed to choose a model, but it does not remove ownership of the decision. AWS’s documented router constraints, OpenRouter’s supported model pool and RouteLLM’s learned preferences all define which alternatives the router can consider; none can label the acceptable answer for a company’s refund policy.
The support-ticket log is the deciding artifact. If it can show the route taken, the route that should have been taken, every paid call and whether the final answer passed, the cost claim is testable. If it records only the selected model and its invoice, the savings are an assumption.
Questions people ask
How much production traffic should run through both models?
Run the full offline test set through both models before launch, then shadow a sampled share of production traffic. Choose the sample from traffic volume and the rarity of high-risk cases, and stratify it by ticket type so uncommon policy exceptions do not disappear inside a large pool of routine requests.
Can a model grade the router’s decisions?
Yes, a model judge can apply a fixed rubric at scale, but teams should compare its grades with human review before relying on it. Recheck disagreements and a continuing sample because model judges can favor verbose answers, miss policy details or rate outputs from related models inconsistently.
When is model routing not worth deploying?
Routing is usually not worth the added system when nearly every request needs the stronger model, model prices are close, or wrong answers carry more cost than the available evaluation can measure. In that case, one model produces a clearer bill, a shorter latency path and fewer hidden failure modes.
What metric should decide whether the router ships?
Use cost per accepted answer, paired with a separate ceiling for false-cheap routes. Compare both with the all-strong-model baseline on the same prompts, tools and rubric; a lower cost per call is insufficient when the routed workflow creates more rejected answers or paid escalations.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.