AI Can Read a PDF. Page Layout Still Decides Accuracy
Native PDF input removes a preprocessing step, but it does not remove layout errors. The right input format depends on whether the document contains tables, columns, scans or citation-sensitive text.
August 17, 2026 · 8 min read
Multimodal models can now accept a PDF directly, which makes document analysis look like a one-step job: attach the file, ask a question and receive an answer. The upload is new convenience. It is not a guarantee that the model sees the page the way a person does.
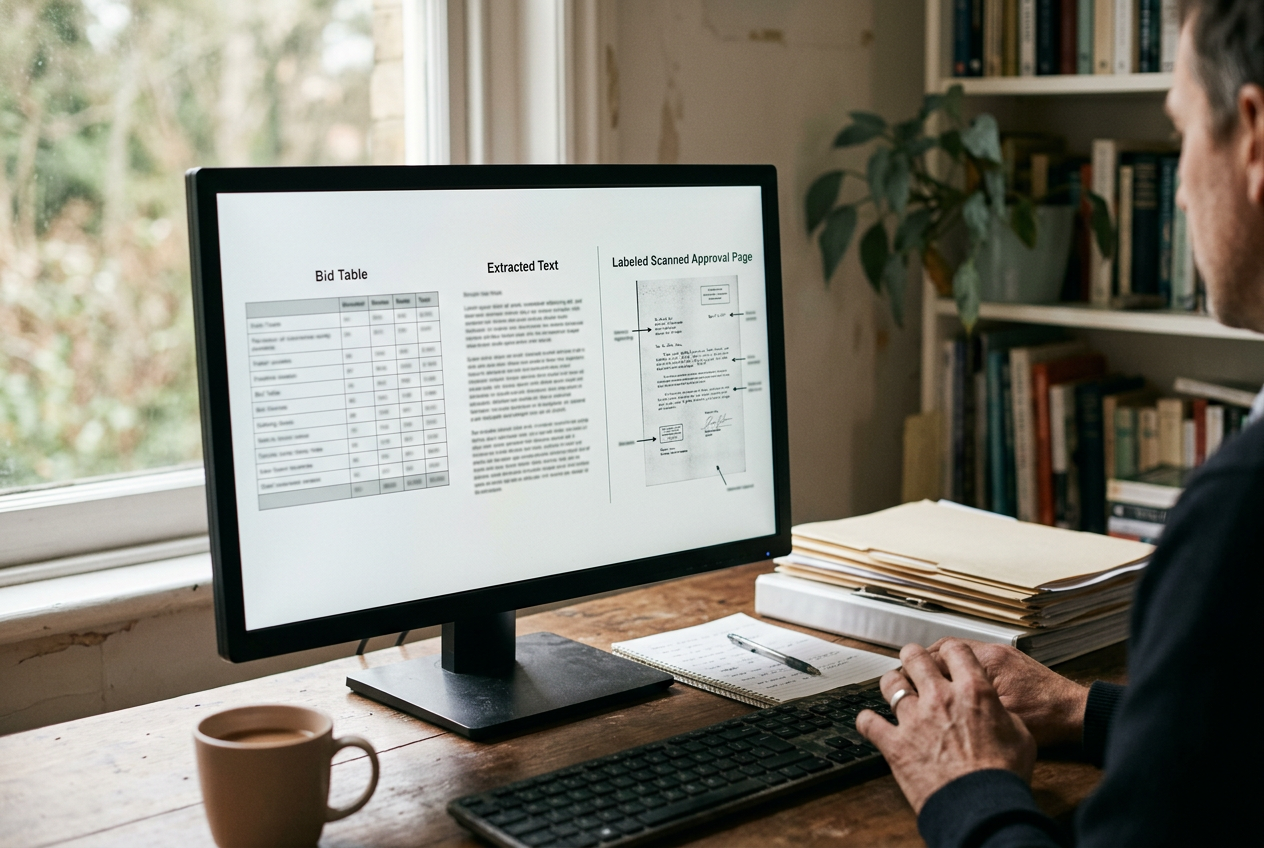
I tested that distinction with a synthetic procurement packet built around one practical task: identify the lowest qualifying bid, explain the relevant contract exception and cite the source page. The packet mixed a bid comparison table with two-column terms, a footnote that changed one price condition and a scanned approval page. Each feature carried information that could alter the final recommendation.
I sent the same packet through three paths. The first supplied the PDF as a native file. The second extracted its machine-readable text before prompting. The third converted each page into an image and labeled the images by page number.
I checked the answers against the visible document rather than grading style or general plausibility.
This was a workflow test, not a model benchmark. A different model, PDF renderer or extraction library can change the result, while repeated runs can expose additional variation. The useful finding was more durable: each input path discarded or obscured a different kind of evidence.
Native PDF input kept the most context
The native upload produced the best first-pass account of the procurement packet because the model could use both embedded text and visible layout. It connected the bid table to the footnote below it, followed the two-column terms in their intended order and recognized that the scanned approval page belonged to the same document.
That makes native input newly practical for ad hoc review. A user can inspect a contract, technical paper or policy packet without first choosing an optical character recognition tool, writing an extraction script or deciding which pages deserve image processing. For mixed office documents, that removed setup is valuable.
The catch is that “native PDF” describes an interface, not one standardized reading method. A provider may extract text, render pages, pass both representations to the model or alter its treatment according to file size and page content. The user often cannot see which path was taken. When the procurement answer looked correct, I could inspect its citations; I could not inspect an intermediate representation showing how every table cell had reached the model.
That opacity matters around tables. The model preserved the visible row and column relationships in this packet, but a table with repeated headers, merged cells or content continuing onto another page can still break those relationships. A fluent answer may then combine a supplier name from one row with a price from the next. Native input lowers the preprocessing burden.
It does not eliminate verification.
Extracted text was leaner and lost the page
The text-only path exposed the central tradeoff. Text extraction, which reads the character layer stored inside a PDF, gave the model clean searchable prose without charging it to interpret every page as an image. For digitally created documents with ordinary paragraphs, this path usually sends less material and avoids visual processing, which can reduce latency and usage compared with rendering every page.
The procurement packet was not ordinary prose. Its extracted table arrived as a sequence of supplier names, prices and qualification notes whose spatial relationships had weakened. The model could still discuss the bids, but the source no longer expressed every association clearly enough to trust the selection without returning to the page.
The footnote suffered differently. Its words survived, yet extraction moved them away from the price marker that gave them meaning. A person looking at the page sees the superscript and immediately knows which number the note modifies. In a flat text stream, the model must infer that link from order, wording or a surviving marker.
That inference can be wrong even when every character was extracted correctly.
Columns created another failure mode. PDF files often store text according to internal object order rather than human reading order, so extraction can place the first line of the right column before the second line of the left one. The resulting text contains real sentences in an unreal sequence. Language models are good at repairing mild disorder, which is useful, but that same ability can hide the damage by producing a coherent interpretation that the page never stated.
The scanned approval page contributed almost nothing to basic extraction because it contained pixels rather than a usable character layer. Optical character recognition, or OCR, can turn those pixels into text, but OCR adds another model and another place for names, totals or checkboxes to be misread.
Text extraction still wins for a large class of work. If a PDF is digitally generated, mostly linear and needed for search, summarization or clause retrieval, extracted text gives the pipeline a visible artifact that developers can log, chunk and compare. Keep explicit page separators during extraction. Without them, even a correct answer cannot reliably point a reviewer back to its source.
Page images made geometry explicit
The image path treated each procurement page as a picture. That preserved the table grid, the footnote’s position and the two-column layout, while the scanned approval page required no special branch because it was already visual material.
Page images also offered the cleanest citation control in this test. Each image carried a page label in the prompt, so the requested citation could be checked against one bounded source. If a workflow must produce page-level evidence for a reviewer, splitting a PDF into labeled images makes the page boundary explicit rather than relying on the model or extractor to reconstruct it.
The cost is input volume. A page image carries typography, margins, logos and other pixels that extracted text does not need. Higher resolution helps with small footnotes and faint scans, but increases transfer size and visual token use, the model-specific units charged for image interpretation. Lower resolution is cheaper and faster until a decimal point, superscript or checkbox becomes unreadable.
There is no universal setting because the smallest consequential mark differs by document.
Images also weaken exact text handling. A model may read a paragraph correctly enough to summarize it while changing punctuation, spacing or a digit in a quoted clause. If the output needs verbatim quotations, searchable offsets or automated comparison against source text, an image-only pipeline creates extra work. Pairing page images with OCR text can recover those functions, though the pipeline must preserve which text came from which page.
For the procurement packet, images were most useful as a targeted fallback rather than the default for every page. The table, footnote and scan justified visual processing. Pages of linear contract language did not. Rendering only the pages whose layout carried meaning retained the verification benefit without paying the full image cost across the document.
Choose the path from the failure you cannot accept
The practical choice starts with document structure, not model branding. A digitally generated report made of headings and paragraphs should usually enter as extracted text with page markers. That path is inspectable, economical and easy to search. Sample the output before deployment because a PDF that looks linear can still store its characters in a broken order.
Use native PDF input when the file mixes prose with tables, illustrations, irregular positioning or occasional scans and the task is exploratory. It offers the strongest balance between setup effort and coverage. Require page citations in the prompt, then verify consequential figures against the rendered source. If the API does not expose page boundaries or its citations drift, the convenience is not worth much for review work.
Choose labeled page images when the visible arrangement is itself evidence, as it was in the procurement table, or when most pages are scans. Images are also the safer route when signatures, checked boxes, stamps or handwritten additions determine status. Budget for more input and keep the original page dimensions readable; aggressive downscaling can erase precisely the mark the model needs.
A hybrid pipeline is the defensible production setup for mixed packets. Extract text with page separators first, route visibly complex or text-empty pages through image analysis, and retain both representations beside the answer. The application can use text for retrieval while presenting the page image for verification. That design adds preprocessing, but it makes errors traceable instead of burying them inside a native upload.
The procurement workflow therefore ended with two checks rather than one universal format. Native PDF handled the initial review. Labeled images backed the table and scanned page, while extracted text supplied searchable contract language. The model still wrote the answer; page structure decided which evidence it could safely use.
Questions people ask
Is native
PDF input more accurate than extracted text?
It was the better default for this mixed-layout packet because it retained visual relationships that flat text lost. For digitally generated prose with a clean reading order, extracted text can be equally useful while remaining easier to inspect, search and cite.
Should every PDF page be converted to an image?
No. Page images preserve tables, columns, scans and positional clues, but they increase input volume and can weaken verbatim text handling. Render the pages where layout changes meaning, then use extracted text for ordinary paragraphs unless the entire document is scanned.
How should a PDF workflow preserve citations?
Keep page boundaries through every preprocessing step and ask for the page beside each consequential claim. Labeled page images give the clearest page-level check, while extracted text needs explicit separators or metadata so a quotation can be mapped back to the rendered source.
What should teams verify manually?
Check table row associations, footnote links, small numeric marks and any content recovered from a faint scan. In the procurement packet, those details could change which bid qualified, so a fluent summary without a visible source page was not enough.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.