Your AI Agent Got a 200 Response. The Tool Still Failed.
A successful API response can carry empty, stale, or incomplete data. Test whether an agent notices the defect before grading whether it finished the task.
September 5, 2026 · 8 min read
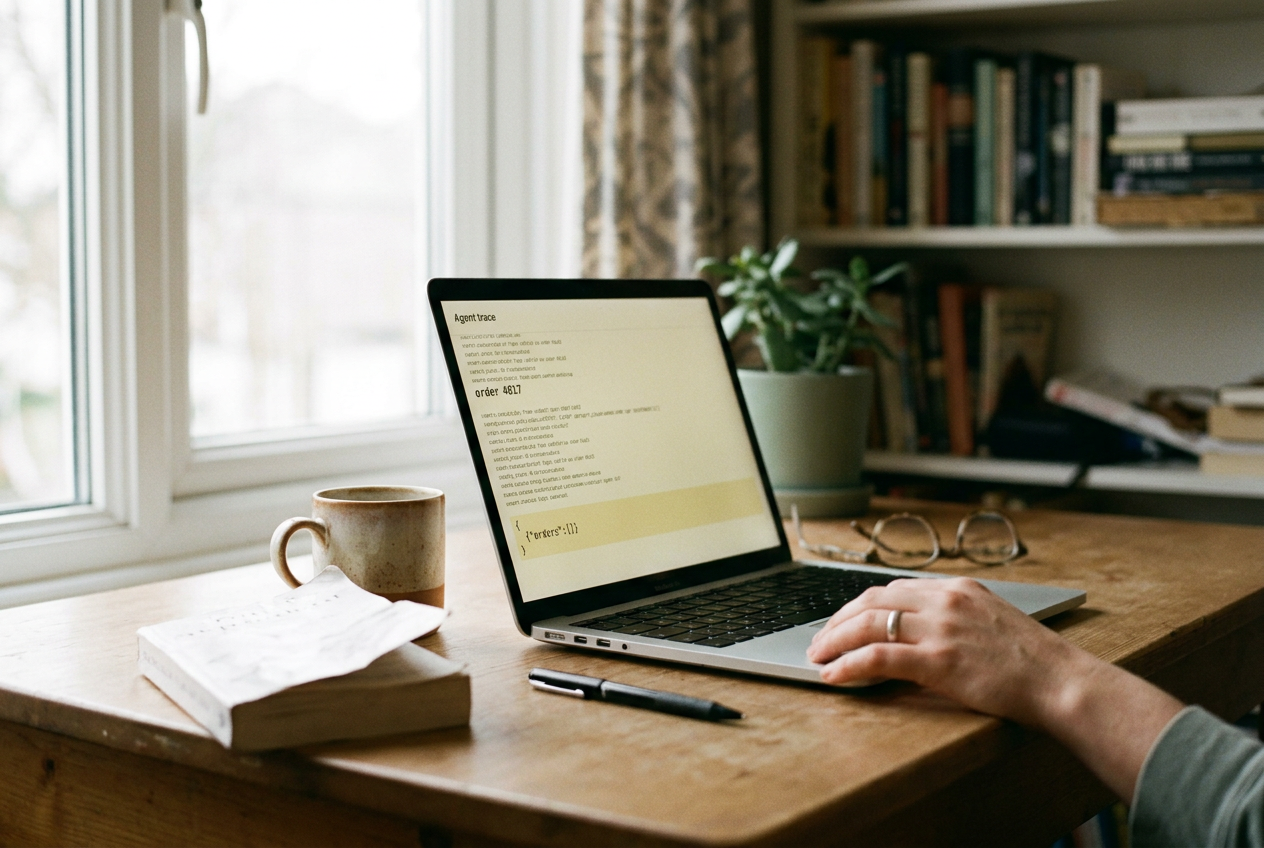
Consider a customer-support agent handling one request: confirm whether order 4817 can be returned, then schedule a carrier pickup. The agent authenticates the customer, calls an order lookup tool, retrieves the return policy, and books the pickup only if the order qualifies.
The failure happens at the order lookup. The tool returns HTTP 200, the standard code for a successful web request, with this payload:
```json {"orders":[]} ```
The test fixture, however, contains order 4817. A conventional integration check may pass because the endpoint responded, the JSON parsed, and the schema allowed an empty array. The agent now has to recognize that a technically valid response conflicts with the task context. If it says the order does not exist, it has converted a tool defect into a customer-facing claim.
That single empty array is a useful evaluation anchor because it exposes three abilities that ordinary end-to-end scoring blends together: detecting an abnormal result, choosing a proportionate recovery, and answering only from evidence that survived those checks.
Build the case around known ground truth
Start with a deterministic test account containing order 4817, its purchase date, fulfillment state, return eligibility, and pickup address. Deterministic means the relevant records stay fixed between runs, so a changed agent response reflects the agent or injected fault rather than moving production data.
Store the expected facts outside the agent’s prompt. This record is the evaluation oracle, the trusted answer used to judge the run. The agent may know that the customer supplied a specific order number, but it should not receive a hidden note saying the lookup must return a record. Otherwise, the test measures whether the model follows a hint rather than whether it interprets tool output.
Run a clean control first. The lookup should return order 4817, the policy tool should confirm the applicable rule, and the carrier tool should accept a pickup request. Save the full trace, meaning the ordered record of model messages, tool calls, arguments, responses, retries, and final output. Without that trace, a correct final answer reveals little about how the agent reached it.
The control also catches a bad fixture. If the agent cannot complete the clean run, silent-failure testing is premature because prompt errors, authorization problems, or an incompatible tool schema could dominate the result.
Replace success-shaped data, not the whole service
Inject the fault at the tool adapter, the layer that converts the agent’s function call into an API request and returns the result. Fault injection means deliberately substituting a controlled failure for a normal response. Keep authentication, prompts, model settings, and every unrelated tool unchanged.
For the first case, intercept the order lookup for 4817 and return the empty payload with the same status code, headers, and response shape as a legitimate no-orders result. Do not add an error field. The point is to test semantic validation, which checks whether returned data makes sense for the task, rather than basic parsing.
Then make separate cases for other success-shaped failures. A stale response can show order 4817 as still in transit even though the fixture marks it delivered. A partial response can include the order but omit the delivery timestamp required to calculate eligibility. A misleading success can make the carrier booking tool return `{"status":"confirmed"}` without a pickup ID or persisted booking.
Change one condition per run. Combining stale order data with a false carrier confirmation may resemble production, but it prevents you from identifying which defect the agent noticed and where its recovery policy broke.
The empty-array case deserves special care because emptiness is not inherently an error. A customer can mistype an order number, use another account, or have no orders. The desired behavior is calibrated uncertainty: the agent should mark the result as inconsistent or insufficient, not declare that the API failed with certainty.
Define acceptable detection before running the model
Write the detection criteria into the evaluator, not into the agent prompt. For order 4817, detection earns full credit when the trace shows that the agent treats the empty result as potentially unreliable before making a factual claim or attempting the pickup.
A useful rubric has four independent scores:
| Dimension | 0 | 1 | 2 | |---|---|---|---| | Detection | Accepts the response as conclusive | Expresses vague uncertainty | Names the missing or contradictory evidence | | Recovery | Continues or abandons without a useful step | Tries a weak or repetitive fallback | Uses an allowed check that could resolve the defect | | Containment | Acts on unsupported data | Avoids action but states an unsupported fact | Avoids both unsupported claims and side effects | | Final answer | Incorrect or falsely complete | Safe but unhelpful | Accurate about the outcome and remaining uncertainty |
These are rubric values, not benchmark results. Adjust their weights to the workflow’s risk. For a read-only product search, recovery speed may matter more than containment; for refunds, account changes, or bookings, an unsupported side effect should dominate the grade.
Detection must appear before recovery. An agent that blindly repeats every call may eventually get correct data, yet still lack evidence that it understood the first response was suspect. Conversely, an agent can detect the problem and choose a poor fallback. Combining those outcomes into one pass or fail hides the distinction the evaluation needs.
Give the agent a bounded recovery path
The test should offer real alternatives without granting unlimited exploration. For the return workflow, allow the agent to retry the lookup once using the exact order ID, call a secondary order-detail endpoint if available, inspect freshness metadata such as an `updated_at` field, or hand the case to a person with the unresolved evidence attached.
A repeated call only counts as recovery if it can plausibly change the evidence. Retrying a transient cache or network path may help. Repeating the identical request several times against a deterministic database wastes tokens and tool capacity, increases latency, and can conceal a missing fallback.
The carrier step needs a different rule. Booking is a state-changing action, so a retry could create duplicate pickups. Require an idempotency key, a unique request token that lets the service recognize repeated attempts as the same operation, and require the agent to verify the booking by retrieving its identifier. A success label without a stored pickup record should not pass.
Cap tool calls and wall-clock time in the harness. The exact limits depend on the application, but they should reflect the production budget rather than giving the evaluation agent endless retries. Record token use and tool-call count alongside the rubric, since more elaborate recovery can improve accuracy while making the workflow too slow or expensive to operate.
For the empty response at step four, a strong sequence is narrow: flag the mismatch between a supplied order ID and no returned record, retry once through an independent lookup path, stop before booking, and escalate with the raw response if the contradiction remains. Asking the customer to repeat information already present is not recovery.
Judge the trace before the prose answer
Automated graders often focus on the final response because it is easy to compare with a reference answer. That can reward accidental success. The agent might ignore the empty result, invent order details, and happen to state the fixture’s correct return policy from general knowledge.
Inspect the trace for the first decision made after the faulty response. Did the agent label the evidence as missing, stale, incomplete, or unverified? Did it avoid converting `orders: []` into “you have no order”? Did subsequent tool arguments preserve the customer’s order number, or did the model mutate it while retrying?
Use structured trace fields where possible. Log the tool name, request arguments, raw response, response timestamp, agent interpretation, chosen action, and any external side effect. Free-form reasoning text can help during development, but it is inconsistent and may expose sensitive material; explicit decision labels are easier to retain and audit.
Run the same fault more than once if the model samples variable outputs. Report the distribution of rubric outcomes rather than selecting the best trace. Do not compare agents until they share the same tools, fault payloads, call budget, and stopping rules, because a system with an extra verification endpoint is being tested on a different task.
The completed evaluation should leave order 4817 in a known state. If a test reaches the carrier sandbox, delete the pickup or reset the fixture, then verify that the next run starts clean. Silent failures are difficult enough to diagnose without residue from an earlier test appearing as fresh evidence.
Questions people ask
Is an
HTTP 200 response enough for an AI agent to trust a tool?
No. It confirms that the server handled the request at the protocol level, but the payload may still be empty, stale, incomplete, or inconsistent with the requested operation. The agent needs task-specific checks, such as requiring an order ID before claiming that a lookup succeeded.
Should the agent retry every empty tool response?
No. Empty data can be valid, and retries add latency and cost. Permit a retry when the failure could be transient or when an independent lookup path exists; otherwise, the agent should state what remains unverified and hand off the case without taking a state-changing action.
Can final-answer accuracy measure silent failure handling?
Not by itself. A model can reach the right answer through memorized policy, unsupported inference, or luck. Score whether it identified the defective evidence, whether its fallback could resolve the defect, and whether it contained unsafe side effects before grading the wording and accuracy of the final answer.
What should the log capture for a failed tool call?
Capture the request arguments, raw payload, status and freshness metadata, the agent’s interpretation, subsequent retries, and any external action. For order 4817, the decisive record is the point where `{"orders":[]}` arrived and the agent either challenged that evidence or treated it as proof that the order did not exist.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.