Visual AI Agents Still Lose the Checkout Button
A moved control is the easy case. Modal windows, sticky banners, and responsive layouts show why visual browser agents need bounded tasks, state checks, and a selector-based fallback.
September 29, 2026 · 8 min read
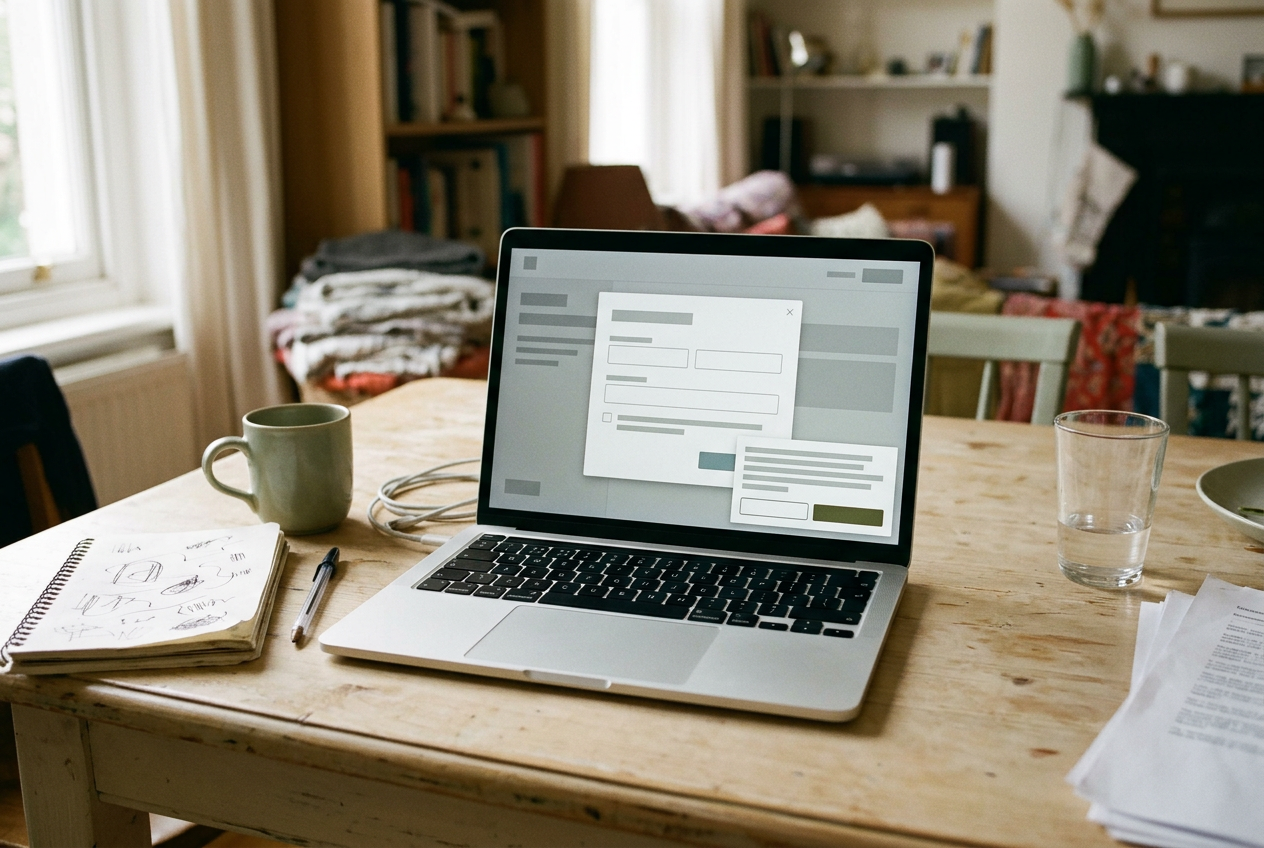
Consider one ordinary workflow: open an account portal, change the shipping address, and press Save. The original page puts the address form under a visible Account menu. A redesign moves Account behind an avatar, opens the form in a modal window, adds a cookie banner at the bottom, and collapses the navigation when the browser narrows.
A selector-based script, which targets a page element through an identifier or document structure, may fail as soon as the old Account selector disappears. A visual computer-use agent has another route. It receives a screenshot, identifies controls from their appearance and text, moves the pointer, clicks, and inspects the next screenshot before choosing another action.
That makes the visual agent less dependent on the page's internal structure. It does not make the agent independent of the interface.
A moved button is the favorable case
If the redesign changes only the Account button's position, visual reasoning has a clear advantage. The agent can search the screenshot for a familiar label or icon without knowing whether the underlying page uses a button, link, nested division, or custom web component. A brittle selector tied to the old location cannot do that unless the automation author anticipated the new structure.
The shipping-address workflow also exposes the limit of that advantage. Finding Account is only one step. The agent must infer that an unlabeled avatar now contains the menu, distinguish Shipping address from Billing address, enter text without replacing the wrong field, and verify that Save committed the change rather than merely closing the form.
Visual agents commonly work in a repeated loop: capture the screen, ask a model to interpret it, choose an action, execute that action, then capture the resulting state. Each loop adds model inference, image transfer, and browser-control overhead. A selector script can click a known element as soon as the browser exposes it. The visual route therefore pays a latency and compute cost even when both approaches succeed.
That cost matters in long workflows. One uncertain menu can trigger several screenshots and exploratory clicks, while a selector-based system either completes the step quickly or raises a clean error. The visual agent's flexibility changes the shape of failure: fewer immediate crashes from changed markup, but more wandering, retries, and plausible actions taken in the wrong state.
Modal windows create state errors
The redesigned address form opens in a modal, a window layered over the current page that usually blocks interaction with the content behind it. Humans recognize the layer from its border, dimmed background, close icon, and focus. A visual agent has to infer the same state from pixels.
This can work well when the modal is large, centered, and clearly titled. It becomes less predictable when the window appears near the edge, uses the same background as the page, or leaves controls behind it partly visible. The agent may click a visible Save button from the underlying account page rather than the modal's Save button, especially if both carry the same label.
The resulting screenshot may still look reasonable. The modal might remain open because validation failed, close without saving, or display a message outside the cropped area. A system that treats any visual change as progress can move on while the old shipping address remains in place.
The practical defense is a state assertion, a check that confirms a required condition before the workflow advances. After Save, the agent should reopen or reread the shipping address and compare the displayed value with the requested value. A toast notification saying “Saved” is weaker evidence because it can disappear before inspection, refer to another setting, or report that the request was accepted rather than persisted.
This is where pure visual operation starts to look wasteful. If the browser can expose the modal title, field names, and saved address through the accessibility tree, which is the structured representation used by assistive technologies, the agent can use that information to confirm state without interpreting every pixel. Vision remains useful for locating the unexpected layer; structured data is better for checking what it contains.
Banners turn geometry into a moving target
A sticky banner stays attached to an edge of the viewport while the page moves underneath it. In the address workflow, a cookie notice at the bottom can cover Save without removing the button from the page. A selector script may find the button and attempt to click it, only for the banner to intercept the click. A visual agent can see the obstruction and dismiss it first.
That is a genuine recovery capability, provided the dismissal control is legible and the agent understands the banner's role. If the notice offers Accept, Reject, Manage settings, and a small close icon, the agent now faces a policy decision as well as a navigation problem. Clicking the most visually prominent option may violate the operator's privacy preference.
The workflow therefore needs a rule outside the model, such as reject nonessential cookies when that control is available, otherwise stop for approval. Visual reasoning can identify the controls. It should not invent the preference.
Banners also expose coordinate drift. Some computer-use systems predict a point on the screenshot and send that coordinate to the browser. If the page scrolls, the banner animates, or the viewport changes between observation and click, the intended point may land on another control. A fresh screenshot before a consequential click reduces this risk, but adds another inference cycle and still cannot eliminate movement between frames.
For low-impact navigation, a retry may be acceptable. For Save, Delete, Submit, or Purchase, the safer design is to locate the control visually, bind it to a structured element if possible, and confirm its label and enabled state before activation.
Screen size changes the interface, not just the picture
Changing the browser width does more than move controls. Responsive design can replace desktop navigation with a compact menu, shorten labels, reorder sections, or remove secondary actions. The narrow version of the account portal may show only an avatar and a menu icon, while the wide version spells out Account in the header.
A visual agent can sometimes bridge those layouts because it reasons from the task rather than a fixed path. It can open the menu icon, inspect the drawer, and continue toward the shipping form. A selector script written only for the desktop path will fail unless its author added a mobile branch.
Yet screen-size resilience depends heavily on language and context. An icon without an accessible label may be obvious to a person who has seen thousands of similar interfaces but ambiguous to a model faced with several small symbols. Cropping creates another problem: the relevant control may exist below the fold, but the agent has to decide whether to scroll the page, scroll the modal, or open a collapsed section. A wrong choice can leave the workflow in a state that looks new without being useful.
Viewport dimensions should therefore be fixed during production runs whenever possible. Testing multiple sizes remains valuable, but random variation is not a sound resilience strategy. If a service controls the browser, it should standardize zoom, window size, font scaling, and device pixel ratio so the visual agent receives a stable operating surface.
The useful design is hybrid
The choice is not between selectors and vision for an entire workflow. The better boundary sits at each action.
Use selectors, roles, or the accessibility tree when the target has a stable machine-readable identity. They are faster to execute, easier to log, and easier to test. Use visual reasoning when the page structure has changed, an overlay blocks the expected control, or the system must interpret layout rather than retrieve a known element.
For the shipping-address workflow, the agent can first look for a stable Account role or label. If that lookup fails, it can inspect a screenshot for an avatar or menu control, open the redesigned navigation, then return to structured interaction once it finds Shipping address. After editing, it should verify the persisted value through page text or a backend response rather than trusting the appearance of the Save action.
This hybrid approach also produces a better audit trail. A log can record that the expected selector failed, vision selected a menu at a particular screen region, the browser resolved that point to an element, and the final address matched the requested value. A sequence of screenshots alone shows what the agent saw, but may not reveal which element received the click or why the model chose it.
Teams evaluating computer use should preserve those transitions. Recovery rate matters, but so do the number of model calls, repeated actions, unintended state changes, and cases where the agent declared success without verifying the result. A system that eventually reaches the form after wandering through unrelated menus may pass a loose demonstration and still be too slow or unpredictable for routine automation.
The adoption line is fairly plain. Visual computer use is worth adding when websites change often, structured access is unavailable, and occasional recovery has real value. It is a poor replacement for an API or stable browser automation on a workflow the operator controls. In that setting, vision adds cost to solve an interface problem that should have been removed.
For the redesigned account portal, the decisive test is not whether the agent can still find Save. It is whether the system notices the obstructing banner, enters the intended address in the correct layer, and proves that the saved value survived after the modal closes.
Questions people ask
Are visual agents more reliable than browser selectors?
They are more tolerant of changed page structure when labels and visual cues remain recognizable. They are usually slower, and their failures can be harder to classify. Stable selectors or accessibility roles remain preferable for known controls; vision is most useful as a recovery path when those methods stop finding the expected element.
Can a computer-use agent handle pop-ups and cookie banners?
It can detect and dismiss many overlays when their boundaries and controls are visible. The workflow still needs explicit rules for choices such as accepting cookies, rejecting tracking, or closing a warning. Without those rules, the agent may treat the most prominent button as the correct one.
How should teams test agents against website redesigns?
Keep the task constant while changing one interface condition at a time, such as menu placement, modal presentation, banner position, or viewport width. Record whether the agent completed the task, verified the resulting state, repeated actions, or clicked an unintended control. Success without state verification should count as unresolved.
When should an agent hand the task back to a person?
Handoff should occur when the agent cannot identify the active layer, encounters several controls with the same label, or reaches a consequential action without confirming the target and current state. The handoff should include the latest screenshot, attempted actions, and the specific assertion that failed, rather than restarting the workflow.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.