AI Can Read a PDF. OCR Still Wins the Hard Pages
Direct PDF input now handles mixed documents in one prompt. Dense tables, tiny print and page order still justify an OCR fallback, or a pipeline that uses both.
October 29, 2026 · 7 min read
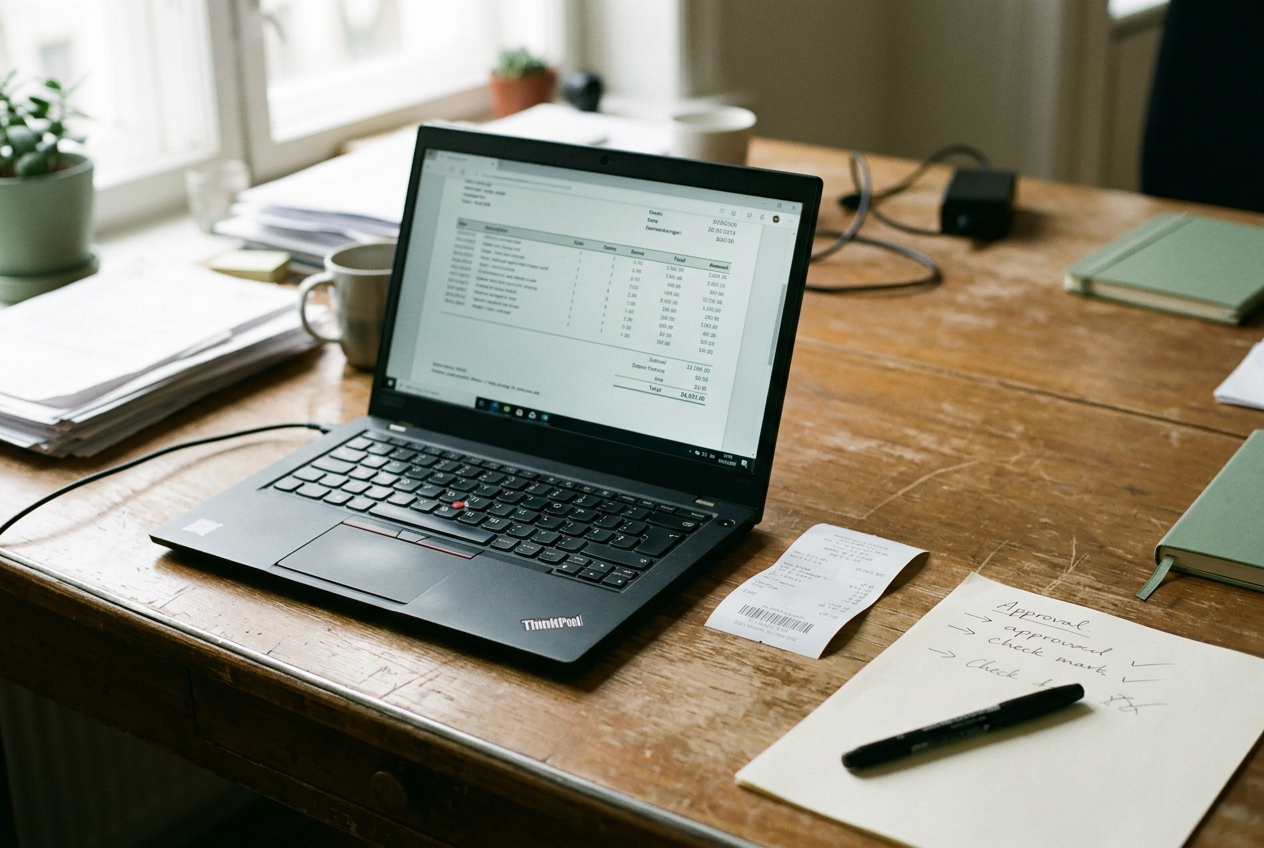
One expense packet exposed the split
The product change is modest but useful: current multimodal systems can accept a PDF or page image directly, rather than requiring a developer to extract every character before asking a question. OpenAI, Anthropic and Google document file or PDF input across parts of their model stacks, although the exact file limits and processing methods vary by product.
That makes a previously awkward workflow practical for a small team. An analyst can upload a supplier packet, ask for the amount due and request a summary of the approval notes without first building a document-processing service.
I tested that workflow with a month-end expense packet containing a born-digital invoice, a photographed receipt, a rate sheet with tightly packed rows, a handwritten approval and appendix pages exported in the wrong order. It was the same packet each time, run through three routes: direct multimodal input, conventional text extraction with optical character recognition, or OCR, which converts pixels into machine-readable text, and a hybrid that supplied both the rendered pages and extracted text.
The prompts asked for specific fields, a transcription of the line-item table, the meaning of the handwritten note and the intended page sequence. This was a workflow test, not a benchmark. One packet cannot establish a general accuracy rate, but it does expose where each route creates review work.
Direct input won the first pass. It required one upload and one instruction, preserved enough visual context to distinguish the invoice total from the subtotal, and connected the approval note to the relevant expense. The same route became unreliable once the task changed from understanding the document to reproducing every cell exactly.
Native input is strongest when layout carries meaning
A PDF is a container, not one kind of page. It may hold selectable text, scanned images, vector graphics and pages assembled from different sources. A multimodal model can use visual features such as position, spacing and typography alongside words, although providers differ in whether they render pages, parse embedded text or combine both internally.
That visual pass mattered on the packet’s invoice. The model recognized that the largest number near the payment block was the balance due and treated a nearby value as a subtotal, even though a plain text extraction placed both numbers in a loose stream. It also associated the handwritten approval with the receipt beneath it instead of treating the note as an unrelated footer.
This is the newly practical part. Direct PDF input works well for discovery, classification and document-level questions where the answer depends on relationships across a page, and it removes a setup stage that once made occasional document analysis disproportionate to the job.
The convenience has a cost. A native model may paraphrase a label, repair an apparent typo or return a plausible value when a character is unclear. Those behaviors help with explanation but damage verbatim extraction. The interface may also resize page images before inference, so a line that remains visible to a person at high zoom can disappear from the model’s effective view.
For the expense packet, direct input was the fastest route to an answer about what the document meant. It was not the route I would use to populate an accounting system without a second check.
OCR keeps an advantage on small print and rigid tables
Conventional document extraction is less ambitious. For a born-digital PDF, a parser first reads the embedded text layer; for a scan, OCR identifies characters from the rendered page. Specialized document systems can also return table cells and bounding boxes, the coordinates showing where each detected item appeared.
That structure gave OCR the edge on the rate sheet. The multimodal pass understood that the page contained item codes, quantities and rates, but it occasionally shifted a value into an adjacent row when the table used narrow spacing and faint rules. Structured extraction retained the row boundaries and made the questionable cells visible for review.
Tiny text produced a similar result. A direct upload asks the provider’s ingestion system to decide how the page should be rendered. An OCR pipeline lets the operator render the page at a chosen resolution, crop the relevant region and retry only that area. Starting around 300 dots per inch is a common document setting; a higher-resolution crop is worth testing when footnotes or compressed labels remain unreadable.
Plain OCR is not automatically better. General-purpose engines can flatten columns in the wrong order, split one table into several fragments or mistake a scan artifact for punctuation. Handwriting remains especially uneven, and a multimodal model may infer a rough note more successfully because it uses surrounding context. In this packet, however, neither route justified unattended transcription of the handwritten approval.
The useful distinction is between interpretation and capture. Multimodal input interprets a page. OCR captures visible strings and, with the right engine, their coordinates. A workflow that requires an exact invoice number has a different tolerance from one asking whether an expense was approved.
Page order needs an external check
The appendix pages in the packet were exported out of sequence. Their printed page numbers indicated the intended order, while their file positions reflected the mistaken export.
The multimodal route noticed the visible numbering when explicitly asked to reconstruct the sequence, but it still described the document in upload order during an earlier summary. OCR extracted the printed numbers yet had no reason to treat them as ordering instructions. Both systems saw evidence of the problem. Neither owned the rule for resolving it.
A reliable pipeline should store two identifiers: the physical index assigned by the PDF file and any printed page label extracted from the page. If those values conflict, the software can flag the packet or apply a documented ordering rule. Letting the language model silently choose creates an audit problem because a later run may make a different decision.
The same principle applies to repeated headers, attachments inserted sideways and forms whose continuation pages omit a title. Page order is document logic. It should not depend only on visual fluency.
The hybrid route earns its extra step
The strongest run used a staged pipeline. It first extracted embedded text from the born-digital pages, applied OCR only to image pages, retained coordinates for the rate sheet and rendered page images for the multimodal model. The prompt then told the model to use extracted text for exact values, images for layout and neither source as authority when they disagreed.
That final instruction matters. Supplying two representations without identifying their roles can make the model choose the cleaner-looking answer, which may be an OCR error with high confidence or a visually inferred value that never appeared in the text. The output should preserve disagreements as fields for review, not smooth them into one response.
For the expense packet, the hybrid route recovered the convenience of document-level reasoning while keeping a traceable source for line items. It also cost more operationally. There was an extraction stage to run, intermediate data to store and a larger model input containing both text and images. Provider billing differs, but duplicate representations generally consume more input than either route alone, while OCR services may add a per-page charge.
That overhead is justified when data will leave the chat and enter another system. A practical implementation can stay narrow:
- Extract the PDF text layer before invoking OCR.
- OCR only pages with no usable text, or regions where extraction failed.
- Send page images when layout, marks or handwriting affect meaning.
- Validate totals, identifiers and row counts with deterministic code, meaning ordinary rules that return the same result every run.
- Route source disagreements to a person instead of asking the model to guess.
The expense packet’s total offered a basic validation rule: add the extracted line amounts and compare the result with the printed subtotal before accepting the model’s summary. That check cannot prove every row is correct, but it catches a shifted decimal or omitted line without another model call.
Choose the route by the output, not the file type
Direct multimodal input is the sensible default for occasional review, document triage and questions where an operator will inspect the answer. One upload is newly practical, and the model’s ability to connect text with layout often beats a plain OCR transcript.
Use conventional extraction when the output must preserve exact characters, table structure or coordinates. If the PDF already contains a sound text layer, skip OCR and parse it directly; running recognition over clean digital text adds another place for characters to change.
Use the hybrid when the document mixes page types or when extracted values feed payments, records or downstream automation. It is slower to build and carries two processing costs, but it separates semantic judgment from transcription and gives reviewers a location to inspect when the sources disagree.
For the rate sheet in this packet, that meant keeping the OCR cell coordinates beside the model’s explanation. A reviewer could click the disputed value, see the original row and correct it without rereading the full PDF.
Questions people ask
Can multimodal AI replace OCR for PDFs?
It can replace a separate OCR step for many summaries, classifications and one-off questions, especially when the PDF contains clear text and meaningful visual layout. It should not be the only extraction layer when exact characters, table cells or coordinates will populate another system.
Why do dense tables still cause trouble?
Small type, weak grid lines and tightly spaced columns can be reduced when a page is rendered for model input. The model may understand the table’s purpose while assigning one value to the wrong row. Structured document OCR preserves cell boundaries and coordinates, making those errors easier to detect.
What is the safest hybrid PDF workflow?
Extract embedded text first, OCR only scans or failed regions, and retain page images for layout-dependent questions. Give each representation a defined role, validate totals and identifiers with deterministic rules, then send disagreements to human review rather than asking the model to reconcile them silently.
Is handwriting better with multimodal AI or OCR?
Multimodal models can use nearby labels and document context to interpret rough handwriting, while conventional OCR often treats it as isolated character recognition. Neither route is dependable enough for unattended capture of approvals, amounts or instructions when the writing is ambiguous; preserve the image and require confirmation.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.