Retiring an AI Model Can Break More Than the API Call
A replacement model may accept the same request while changing refusals, tool arguments, latency, and output structure. Migrate the behavior before you change the model name.
October 24, 2026 · 8 min read
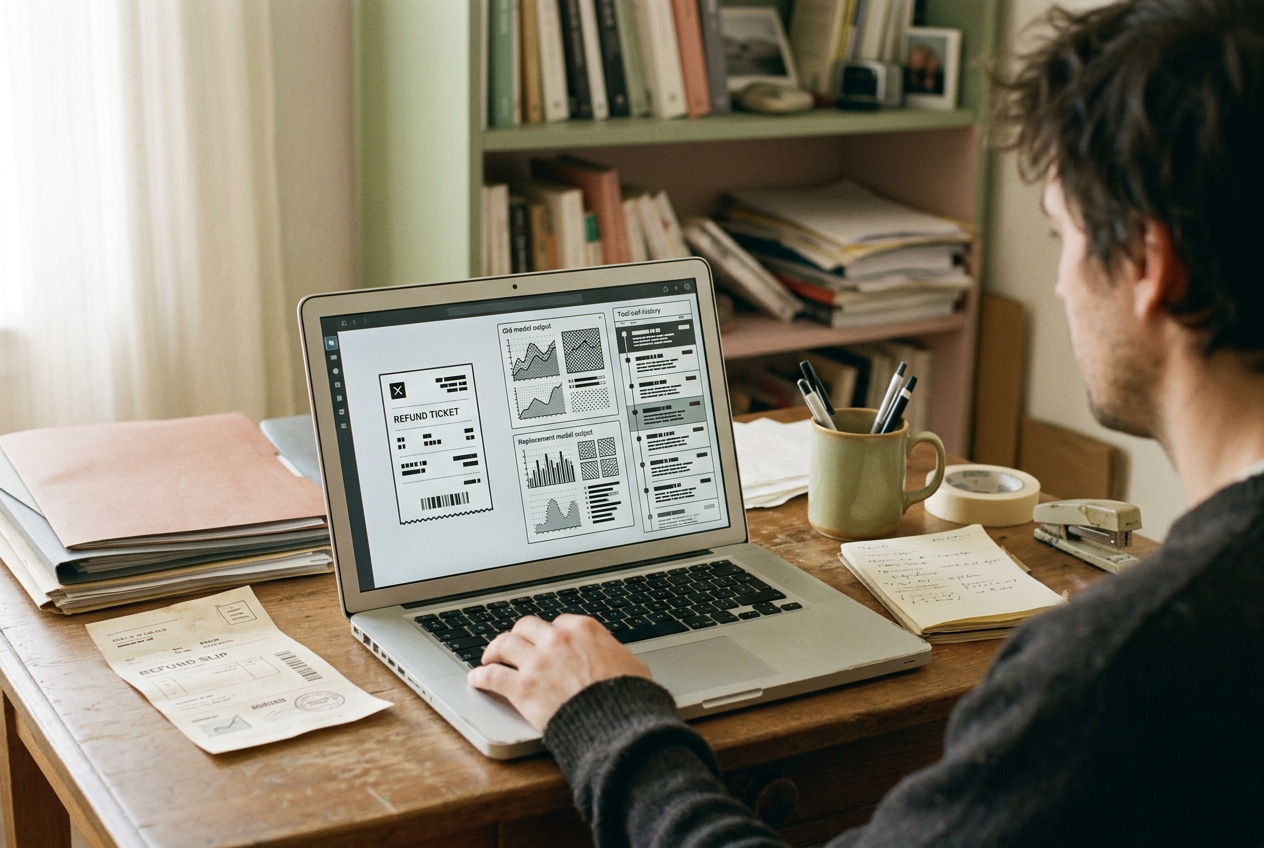
Consider one support-ticket workflow. A customer message enters the application, the model classifies its issue, decides whether to call a refund-status tool, and drafts a reply after the tool returns. The application expects a valid category, a permitted tool call, and language that does not promise a refund before the account system confirms one.
A deprecation notice for that workflow looks like maintenance: replace the retired model identifier with the vendor’s recommended successor. The request may still run. That says little about whether the application still behaves as designed.
Model vendors document that versions differ in capability, instruction following, safety behavior, supported features, and availability. OpenAI, Anthropic, and Google Cloud also publish separate material on model lifecycle, version selection, evaluations, and tool or function calling. Their terms differ, but the operational implication is consistent: compatibility at the API layer does not establish behavioral equivalence.
For the support workflow, a new model might call the refund tool more often, use a renamed argument the application rejects, refuse an angry but legitimate complaint, or produce a longer answer that pushes response time beyond the service target. The migration therefore needs five gates, completed in order, with the old model kept available for rollback until the evidence supports removal.
Turn the notice into a behavior contract
Start with the vendor notice. Record the retirement month or cutoff supplied by the vendor, the recommended replacement, affected endpoints, feature differences, and any change to regional availability or pricing. Treat an alias, which is a model name the vendor can redirect, differently from a fixed version identifier. An alias reduces code churn but can also move behavior without a deployment from your team.
Now write down what the support workflow must preserve. That contract should name observable outcomes rather than broad goals: which ticket categories are valid, when the refund-status tool may run, which arguments it requires, what the application does after a tool error, which requests should receive a safety refusal, and how much response time the product can tolerate.
Set acceptance thresholds before testing the successor. A team could require zero malformed tool arguments on its high-risk refund cases while allowing a small change in wording similarity, for example; the exact threshold belongs to the application, but choosing it after seeing results turns an evaluation into an explanation for a decision already made.
Assign an owner and a rollback deadline as well. The vendor cutoff is the last possible date, not the deployment target. Leave enough calendar space for one failed test round, one prompt revision, and one staged rollout, because a migration discovered during the final week has no safe fallback if the replacement behaves differently.
Freeze representative outputs before they disappear
Create a fixed evaluation set from real, redacted traffic. For the ticket workflow, include ordinary requests, incomplete account details, duplicate refund questions, hostile wording, ambiguous product names, attempts to override system instructions, tool failures, and conversations near the application’s context limit. A context limit is the maximum amount of input and output the model can process in one request.
Sampling only common tickets will hide the cases most likely to change. Build the set across both frequency and consequence: common low-risk messages show whether the general experience moved, while rarer cases involving money, personal data, or account access show whether the application’s controls still hold. If the product serves several languages, preserve examples from each supported language rather than translating an English-only set.
Run that set through the retiring model before access ends. Save the model identifier, system prompt, user input, conversation history, sampling settings, tool definitions, tool results, output text, token counts, errors, and timestamps. If the vendor exposes a seed or other reproducibility control, record it, but do not assume identical settings guarantee identical prose.
The frozen output is evidence, not a gold answer. Models can produce a good result for the wrong reason, and the retiring version may contain behavior the team should not preserve. Label each run with the application outcome: correct classification, permitted tool decision, valid arguments, grounded draft, acceptable refusal, or failure. That converts an archive into a baseline the successor can be judged against.
Return to the refund ticket. A saved draft that sounds polite is insufficient if its tool trace shows the model queried the wrong order. The behavior contract cares about the order identifier and authorization rule before it cares about stylistic similarity.
Compare safety decisions and tool traces
Run the successor against the same inputs with the same prompts, tools, and sampling configuration wherever the new API supports them. Use paired comparison, meaning each old-model run is evaluated beside the corresponding new-model run, so aggregate improvements do not conceal a regression on one important case.
Check safety behavior by outcome. Separate an appropriate refusal from an over-refusal, where the model blocks a legitimate request, and from unsafe compliance. In the support set, abusive wording should not automatically prevent the model from checking an order, while a request to expose another customer’s details should remain blocked even if it is phrased politely. Review changed decisions manually because text similarity cannot tell those outcomes apart.
For tool use, which lets a model request that application code execute a named function, compare the complete trace rather than the final reply. Inspect whether the model called a tool, which tool it selected, the argument names and values, call order, repeated calls, and behavior after an error. Validate arguments against the production schema instead of accepting JSON merely because it parses.
A successor that drafts a better response but doubles unnecessary refund lookups raises cost and load. One that skips the lookup can be worse: it may answer from the ticket text and invent account status. Count tool attempts per completed ticket, schema failures, unauthorized calls, no-call errors, and successful recoveries after the tool returns an error.
Do not edit the prompt at the first mismatch. Run the unchanged baseline first, which isolates the model change; then create a second candidate with any prompt, schema, or retry-policy adjustments. Otherwise the team cannot tell whether the successor differed or the migration itself introduced the regression.
Measure latency as the user experiences it
Measure the full support path, not a single model request. Capture time to first token, total model time, tool execution time, retries, and end-to-end completion. Report at least the median and a tail percentile such as p95, the point below which 95 percent of measured requests finish, because a replacement can improve the typical response while making slow cases worse.
Use production-shaped inputs and concurrency. A short synthetic prompt will not reveal what happens when the ticket includes a long conversation, the model calls the refund system, and a schema error triggers a retry. Compare token use too: longer hidden reasoning or visible answers can increase both latency and billed usage even when the vendor’s per-token rate is lower.
Set separate budgets for interactions that stream text and jobs that run in the background. A slower model may be acceptable for an overnight ticket summary but not for the agent-assist panel that a support representative waits on after opening the case. If the successor misses the interactive budget, test a smaller model, shorten retrieved context, or move nonessential drafting out of the synchronous path.
Stage traffic with an immediate rollback
Begin with shadow traffic, where production inputs are copied to the successor without letting its output affect the customer or invoke live tools. Stub write actions and use read-only tool access where possible. Shadowing reveals output and latency differences, although it cannot reproduce every multi-turn reaction because users never see the candidate response.
Next, send a small slice of eligible live traffic to the successor. A sequence such as 1 percent, 5 percent, 25 percent, 50 percent, and 100 percent can work for a high-volume service, but the gate should also require a minimum case count; at low volume, percentages produce too little evidence. Keep high-consequence refund actions on the old path until lower-risk classifications and read-only lookups pass.
At every stage, compare the successor cohort with the old-model control. Watch application outcomes: escalation rate, malformed arguments, tool retries, refusal changes, completion latency, token use, and human correction. Segment by language, ticket type, input length, and tool path, because a stable overall average can hide a failure concentrated in long conversations.
Wire the rollback to configuration rather than a code release. The switch should restore the old model, its matching prompt, tool schema, and retry policy together; rolling back only the model identifier can create a combination that was never tested. Define who can activate it and which threshold stops the rollout.
Once 100 percent of traffic has remained inside the agreed gates for the observation window, remove the old path before the vendor does. Archive the evaluation set, paired results, approved configuration, and rollout record. The next notice then starts from a documented support workflow rather than a model name someone remembers changing.
Questions people ask
Can
I migrate by changing only the model name?
Only if testing shows the replacement preserves the application’s required behavior. The same endpoint can return different refusals, tool choices, argument structures, token usage, and latency, so a successful API response proves transport compatibility rather than product compatibility.
How many evaluation cases does a migration need?
There is no universal count. Use enough cases to cover frequent requests plus every high-consequence path, then require minimum observations for each important segment during rollout. A set with hundreds of repeated easy tickets is less useful than a smaller set that includes refund authorization, tool errors, long conversations, and safety boundaries.
Should we rewrite the prompt for the replacement model?
Possibly, but first test the successor with the unchanged prompt and tool schema. That run identifies model-driven differences. Test prompt or schema revisions as a separate candidate, then promote the combined configuration only if it improves the defined outcomes without breaking latency, safety, or tool controls.
When is it safe to delete the old model path?
Delete it after the successor has handled 100 percent of eligible traffic for the chosen observation window, all behavior and latency gates remain within threshold, and the vendor cutoff no longer threatens an emergency rollback. Until then, keep the old model’s prompt, schema, and configuration behind one tested switch.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.