Real-Time Voice APIs Cut Two Handoffs but Blur the Audit Trail
Direct audio models can replace a three-stage voice stack with one live session. The payoff is quicker turn-taking; the cost is weaker transcript and moderation control.
October 13, 2026 · 8 min read
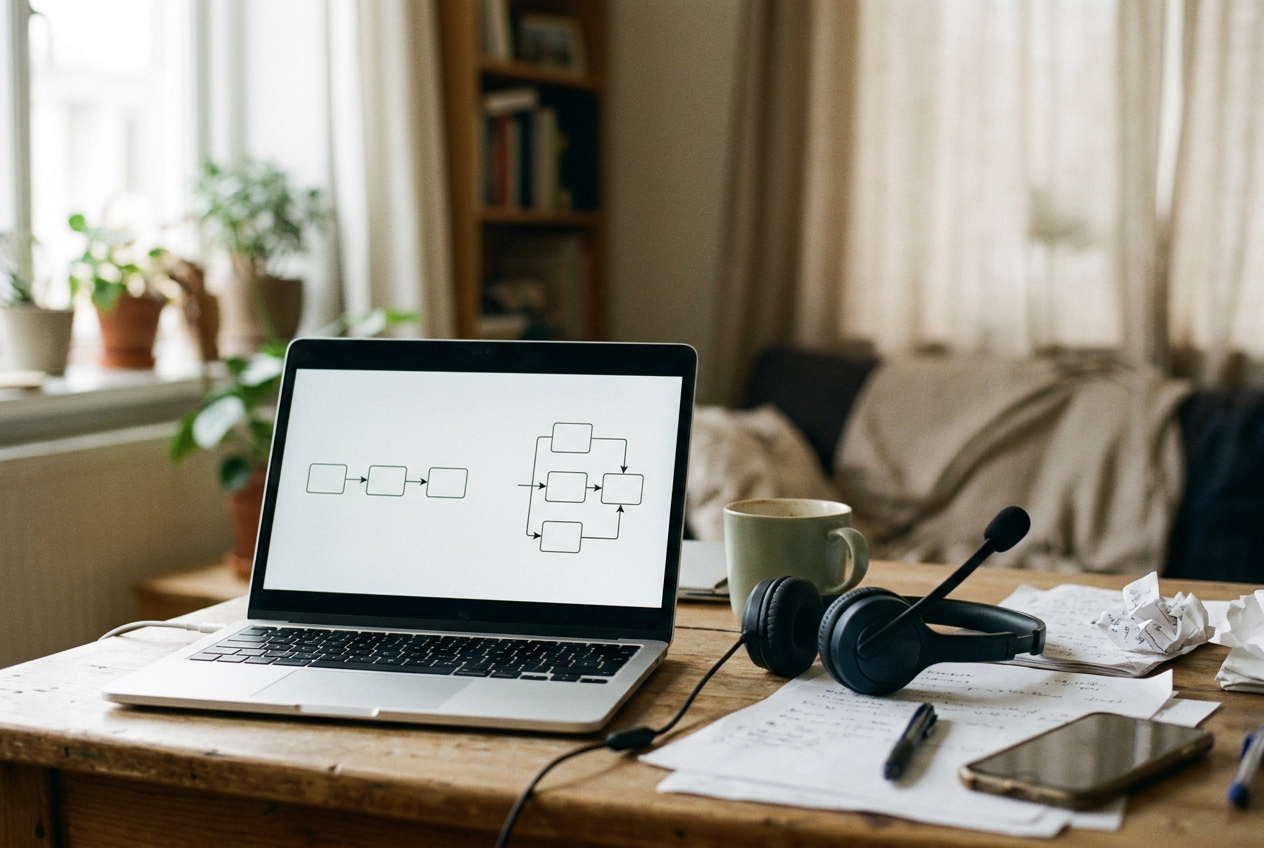
Put one test call on the desk: a customer phones a delivery company, asks to move tomorrow’s drop-off, gives a new address, then interrupts the agent halfway through its confirmation. The system must hear the correction, validate the address through a tool, update the order only after confirmation, and leave enough evidence for a supervisor to reconstruct the exchange.
That call used to imply three model stages. Automatic speech recognition, or ASR, turned the caller’s audio into text; a language model produced a text reply; text-to-speech, or TTS, rendered that reply as audio. Real-time speech-to-speech APIs can now accept audio and produce audio inside one persistent session, with tool calls inserted when the model needs outside data.
OpenAI introduced its Realtime API in public beta in October 2024 and subsequently documented browser connections over WebRTC, server connections over WebSocket, and SIP connections for telephony. Google’s Live API documentation describes the same broad change: a bidirectional session can process streaming audio and return audio without requiring developers to assemble separate recognition and synthesis services.
What becomes practical is a phone agent that handles interruption and resumes after a database lookup without two extra model handoffs. What does not arrive automatically is a trustworthy written record of what the caller said or what the model appeared to hear.
The two architectures
The conventional cascade exposes every intermediate artifact:
```text Caller audio | v [1. Speech recognition] | timestamped transcript v [2. Text model] <------> order and address tools | approved text reply v [3. Speech synthesis] | v Caller hears audio ```
This design has three model stages and two internal handoffs. The application can store the recognized words, run text moderation before generation, inspect the proposed reply before playback, and replace any stage without replacing the other two. It also waits for each boundary, although streaming ASR and streaming TTS can overlap some work.
The direct path is shorter:
```text Caller audio | v [1. Persistent speech-to-speech session] | ^ v | order and address tools | v Caller hears audio
Optional side outputs: - input transcription - output transcription - session events and tool logs ```
The delivery call now crosses one model boundary rather than three. The session detects that the caller has started or stopped speaking, emits audio incrementally, and can cancel an unfinished response when the caller interrupts. OpenAI’s Realtime documentation calls the speech detector voice activity detection, or VAD, and offers server-managed turn detection as well as application-controlled turns.
That removes orchestration work. In the cascade, the application must decide when the transcript is stable enough to send, cancel text generation after an interruption, stop the synthesizer, and keep the next turn from inheriting words the customer never heard. A direct session can coordinate those events against one conversation state.
The address update still needs a separate control boundary. The model should call an address-validation function, receive the normalized result, read it back, and wait for confirmation before an order system commits the change. Speech-to-speech removes media handoffs; it does not make an irreversible tool call safer.
Where the latency goes
A cascade accumulates delay at two joins. Recognition must expose enough text for the language model to act, then synthesis must receive enough output text to begin speaking. Streaming reduces both waits, but every service has its own buffering, network path, retry behavior, and end-of-turn decision.
A direct audio session removes those two joins from the application architecture. It can also use vocal information that a transcript flattens, including pace and hesitation, while returning speech before a complete text answer exists. For the interrupted delivery call, that makes short acknowledgments and corrections feel more practical than a turn-based agent that waits for a finalized transcript.
No vendor document turns that architectural advantage into a universal latency number. Network distance, telephony transport, turn detection, tool duration, and the model selected all remain on the critical path. A slow address API will still create a slow pause. Teams should therefore measure four timestamps from their own call: end of caller speech, first model event, first audible output, and tool completion.
Turn detection deserves its own test. A short VAD timeout answers quickly but may cut off a caller who pauses between a street number and street name. A longer timeout protects the utterance and adds silence before every reply. The useful comparison is not a vendor demo; it is the same scripted address, spoken once fluently and once with a mid-sentence pause.
The transcript becomes evidence from the side
The cascade’s transcript is imperfect, but it is the text that the language model received. That gives a reviewer a direct chain from recognized input to generated reply.
Direct audio breaks that equivalence. OpenAI’s Realtime transcription documentation says input transcription runs asynchronously and should be treated as guidance rather than a precise representation of what the model heard. The audio model consumes audio directly, while a separate transcription process produces text alongside the conversation. Those outputs can diverge around names, addresses, background speech, and clipped words.
For the delivery call, a log might show the correct normalized address from the validation tool even when the side transcript misspells the street. The reverse is more dangerous: the transcript may look plausible while the model acted on a different interpretation. An auditor can replay the recording and inspect the tool arguments, but cannot assume the input transcript is the model’s internal record.
Output transcripts have a related limit. Real-time APIs can emit text associated with generated audio, yet a team that wants to moderate every sentence before the caller hears it must hold the audio until that check finishes. That reintroduces a gate between generation and playback, surrendering part of the latency gain that justified the direct path.
OpenAI’s moderation documentation covers text and image inputs, not live audio. A direct session therefore needs another mechanism for audio review, such as parallel transcription followed by text moderation, post-call analysis, or narrow prompts and tool permissions that reduce what the model can do. None produces the same control as approving text before TTS speaks it.
Cost control shifts from components to conversations
A three-vendor cascade exposes three bills, which is inconvenient but adjustable. A team can route recognition to one provider, reserve a larger language model for difficult turns, and choose a basic voice for routine confirmations. It can cache fixed phrases such as consent notices and operating hours rather than synthesize them repeatedly.
The direct route concentrates audio input, audio output, context, and session behavior in one model family. Vendor pricing pages commonly separate audio from text usage, while tool calls and external telephony remain additional costs. The right unit is the completed call, including silence, interruptions, repeated confirmations, and time spent waiting for tools, rather than the model’s headline token rate.
Run the delivery script at least four ways: a clean call, a noisy call, an interruption, and a failed address lookup. Record total audio usage, tool retries, completion rate, and supervisor review time. A faster model that triggers more manual review may cost more per resolved update even if its model invoice is lower.
The cascade remains the stronger default when one stage dominates cost. If most calls end after a fixed status lookup, cheap recognition plus cached audio may beat a continuous audio model. Direct speech becomes easier to justify when natural interruption, multilingual audio behavior, or reduced orchestration removes enough engineering and abandonment cost to offset the bundled model spend.
A practical split for the delivery call
Use direct speech for the conversational surface, but keep the business action outside it. The session may discuss dates and collect an address; a typed function schema should constrain the order ID, proposed slot, and normalized destination. The application validates those fields, asks for confirmation, then records the final tool result independently of the model’s conversational transcript.
Store five artifacts: the original recording where policy permits it, session events, side transcripts, tool arguments and results, and the final business-system mutation. That set does not recreate the model’s internal interpretation, but it lets a reviewer compare what was audible with what changed in the order database.
A team that cannot retain audio should notice the consequence before choosing the architecture. Without the recording, an asynchronous transcript may be the only readable account of the caller’s words, even though the vendor documentation says it is not equivalent to what the audio model heard. For regulated or heavily disputed calls, that gap can outweigh faster turn-taking.
The desk test has a clear pass condition. After the caller interrupts the first confirmation, no stale audio should continue, no update should reach the order system before the second confirmation, and the logs should identify the exact tool payload that produced the final change.
Questions people ask
Does speech-to-speech eliminate transcription entirely?
It can remove transcription from the critical path, meaning the model does not need recognized text before responding. Teams may still generate a side transcript for search, review, or moderation, but OpenAI’s documentation warns that asynchronous input transcription is not an exact record of what the audio model heard.
Is a direct audio model always faster than a three-stage stack?
It removes two application-level handoffs, which can reduce turn latency and simplify interruption handling. The result still depends on network transport, turn detection, model speed, and tool response time. Measure the interval from the caller’s last audible word to the first returned audio on the production route.
Can teams moderate a voice response before it plays?
Yes, but they must introduce a gate. The application can transcribe or otherwise inspect generated content, approve it, then release buffered audio; that delay gives up part of the direct model’s advantage. Post-call moderation preserves speed but cannot stop a bad response already heard by the caller.
When should a team keep the traditional cascade?
Keep it when an exact text checkpoint, interchangeable vendors, or pre-playback approval matters more than conversational speed. For the delivery call, the cascade is also easier to defend when audio cannot be retained, because its recognition output is the same text passed into the language model.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.