Speech-to-Speech APIs Hide the Transcript You Still Need
Real-time voice models can remove transcription from the application path. For support calls that need moderation and audit logs, developers may still need to generate text beside the conversation.
September 19, 2026 · 8 min read
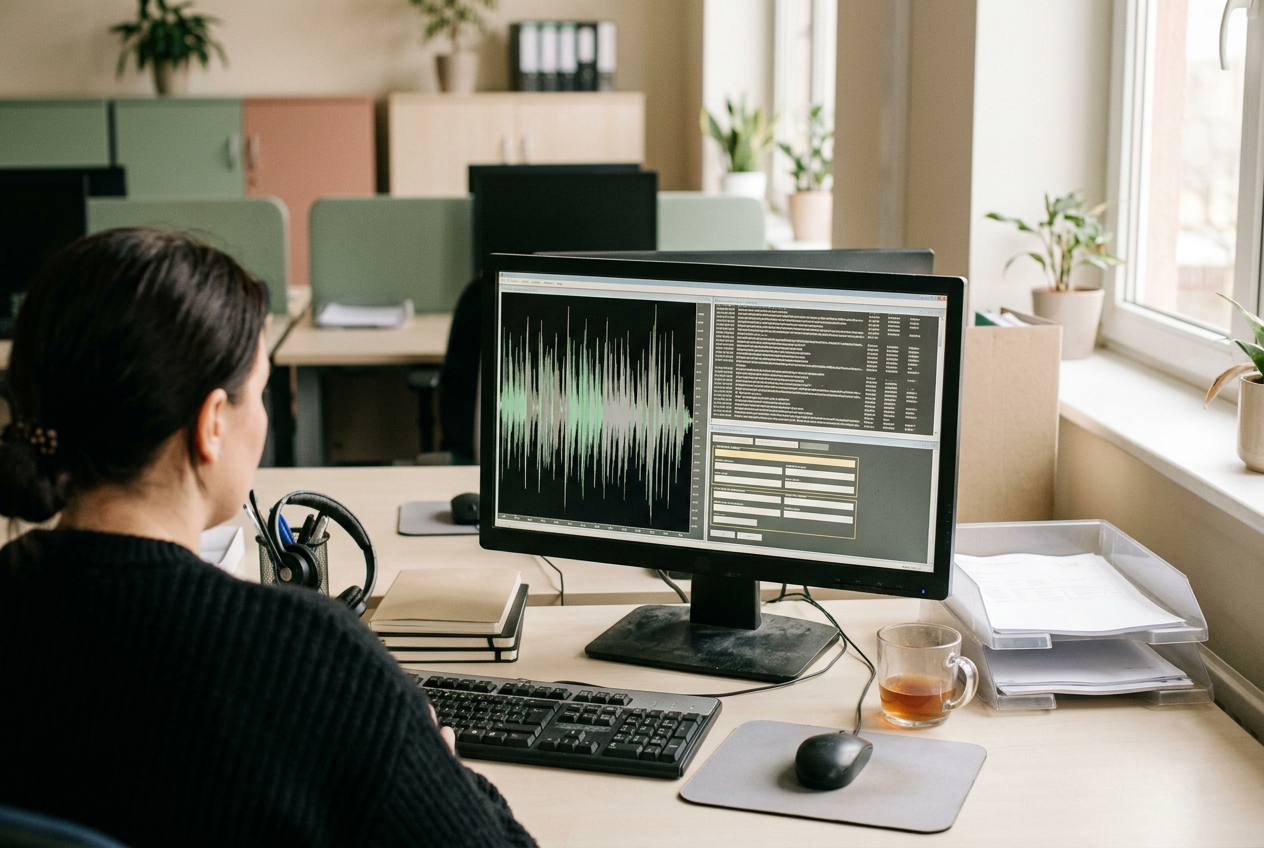
Consider one support call. A customer says, “Change my shipping address to 14 Green Street,” the assistant reads the address back, and a tool updates the order. The company needs the call to feel immediate, but it also needs evidence of what the customer requested, what the model repeated, and which address reached the order system.
In the older voice stack, that evidence appears almost by default. Automatic speech recognition, or ASR, converts the caller’s audio into text; a language model produces a text answer; text-to-speech, or TTS, renders the answer as audio. Each stage leaves an inspectable artifact.
Real-time speech-to-speech APIs change that path. Products including OpenAI’s Realtime API and Google’s Live API accept streamed audio and return streamed audio, while their documentation describes transcription as an optional or parallel capability rather than the mandatory interface between the application and the model. The support application can now pass sound in and receive sound out without handling a completed user transcript before every response.
That makes fluid interruption and faster turn-taking newly practical. It does not prove that no transcription, audio tokens, or language-like representation exists inside the provider’s system. “Speech-to-speech” describes the developer interface and model path exposed by the API, not a guarantee that the service never derives text internally.
Three architectures that can sound the same
A conventional cascade runs the Green Street request through at least three model operations: speech recognition, response generation, and speech synthesis. Streaming lets those stages overlap, but each still has a boundary. The application can reject a faulty transcript before calling the language model, inspect the model’s text before synthesis, or substitute another vendor at one boundary.
A native audio system accepts audio units directly and generates audio units directly. Those units are machine-readable representations of sound, often called audio tokens, rather than a sentence supplied by the application. A unified model can use timing, emphasis, laughter, and other acoustic information that a plain transcript discards, then begin producing speech without waiting for an ASR stage to declare the utterance complete.
The practical distinction appears during an interruption. If the assistant is reading back “14 Green Street” and the customer cuts in after “14,” a real-time session can receive the interruption, stop playback, and continue from the shared conversational state. OpenAI documents WebRTC, WebSocket, and SIP connections for Realtime sessions, while its turn-detection controls determine when the service treats speech as a completed turn. Google’s Live API documentation likewise describes streamed audio sessions and automatic activity detection.
A third design is the hybrid, which is often the sensible choice for the support call. Audio remains on the low-latency path, while a separate recognizer produces input and output transcripts for the log. OpenAI’s Realtime documentation makes an important distinction here: input transcription runs as a separate ASR process and should be treated as guidance rather than an exact record of what the real-time model interpreted.
That warning changes how the Green Street log should be labeled. The transcript is an observation of the audio, not a dump of the model’s internal state. If the voice model acts on “14 Green Street” while the side recognizer writes “40 Green Street,” the tool call and audio recording become the stronger evidence of what happened.
Latency moves rather than disappearing
The cascade has serial work. Recognition must produce enough text for the language model, the model must produce enough text for synthesis, and the synthesizer must buffer enough sound for stable playback. Streaming can start all three early, though corrections at one stage may arrive after the next stage has committed to an answer.
Direct audio removes two application-visible handoffs. That can shorten the pause between the customer finishing and the assistant speaking, and it can preserve cues that text strips away. The remaining delay comes from network transport, audio buffering, turn detection, model inference, and playback.
Turn detection deserves more attention than a headline latency figure. Voice activity detection, or VAD, marks stretches of sound as speech or silence; semantic turn detection also considers whether the utterance appears complete. Aggressive settings answer sooner but may cut off a caller who pauses between “14” and “Green Street.” Conservative settings protect the address and make every turn feel slower.
Developers should therefore test the workflow with the exact audio pattern that matters: a street number followed by a pause, background speech, an interruption during readback, and a correction after the tool call begins. Median response time alone will not expose a system that is quick on ten ordinary turns and wrong on the one turn that changes an order.
Moderation loses its clean checkpoint
The cascade offers a simple control point. After ASR, the application can send the user text to a text moderation system; after generation, it can inspect the proposed answer before TTS speaks it. The cost is another decision in the critical path, plus the recognition errors inherited from ASR.
Direct audio weakens that checkpoint because the response may begin playing before a full output transcript exists. A text-only moderation endpoint cannot inspect tone, non-speech sounds, or words omitted by the side transcript, and moderation that finishes after playback can record a violation without preventing it.
For the support call, the safest design depends on the action. Casual conversation can stream immediately under the voice model’s built-in safety behavior. An address change should pause at the tool boundary, show or read back the normalized address, and require confirmation before execution. This keeps the conversational path fast while putting the consequential operation behind structured text that the application can validate.
Chunk-level output gating is another option: buffer some generated audio, inspect an accompanying transcript, then release the audio. The buffer restores a moderation window by adding delay. If the transcript arrives asynchronously or differs from the generated speech, the gate still cannot offer the same certainty as reviewing a complete text response before synthesis.
A useful log needs more than dialogue text
A cascade can log two text strings and one tool call. A real-time audio session needs a wider event record: session configuration, timestamps for detected speech boundaries, interruptions, optional input and output transcripts, tool arguments, tool results, and identifiers linking those records to retained audio where policy allows it.
OpenAI documents separate Realtime events for audio input, response output, transcription, and function calling. Google documents optional input and output audio transcription for Live API sessions. Enabling those fields makes search and review practical again, but it also reintroduces transcription cost, storage, redaction work, and another model whose errors must be tracked.
The Green Street call illustrates the minimum useful chain. The log should preserve the side transcript as an estimate, the normalized address passed to the order tool, the customer-confirmation event, the tool result, and enough timing information to establish whether the confirmation happened before the update. Saving only “address changed successfully” cannot explain a wrong delivery.
Raw audio offers better forensic evidence than a transcript, but it creates a larger privacy burden and is slower to search. Teams need a retention rule for audio that is separate from the rule for derived text, because deleting one does not automatically delete the other. Consent and recording requirements also vary by jurisdiction and use case, so the API choice cannot settle that policy question.
Debug the waveform, transcript, and action separately
Direct audio complicates reproduction. A text prompt can be copied into a test harness; a voice turn also depends on codec, sample rate, packet timing, background noise, VAD configuration, and where the user interrupted playback. Replaying only the side transcript removes several conditions that may have caused the failure.
For the Green Street incident, debugging should compare three artifacts. The waveform establishes what reached the service. The optional transcript shows what the separate recognizer decoded. The tool arguments show what the model committed to structured form.
A mismatch between the last two is not automatically an ASR bug, because the real-time model and transcription model can interpret the same audio differently.
This is the adoption test. Direct audio is worth considering when interruptions, expressive speech, or short turn gaps materially improve the product, and when the application can preserve structured checkpoints around consequential actions. A cascade remains easier to operate when every utterance must be searched, reviewed before playback, replayed as text, or routed through established text controls.
For a support system that only answers store-hour questions, native audio may remove machinery without creating much new risk. For the address-changing assistant, keep the side transcript, retain the tool trail, and require confirmation on the normalized address. The transcript has left the interface, but the operational need for inspectable text has not.
Questions people ask
Does speech-to-speech mean the model never creates text?
No. It means the application can send audio and receive audio without using a transcript as the required interface. A provider may use audio tokens, internal language representations, or separate transcription models; vendor APIs generally do not expose enough of the internal pipeline to prove that no text-like representation exists.
Is a side transcript an exact record of what the voice model heard?
Not necessarily. OpenAI’s Realtime documentation distinguishes input transcription from the model’s own audio processing and warns that the separate transcript may diverge. Treat it as searchable evidence, then use the recording, event timing, confirmation step, and structured tool arguments to investigate consequential errors.
Can direct audio still be moderated before users hear it?
Yes, but pre-playback moderation usually requires buffering audio or waiting for an accompanying transcript, which adds latency and may miss information the transcript did not capture. A practical design streams ordinary conversation while holding tool execution and other consequential outputs behind validation and explicit confirmation.
When should a team keep the older ASR-to-model-to-TTS pipeline?
Keep the cascade when inspectable text is a hard requirement at every turn, existing controls operate on text, or failures must be reproduced from prompts alone. Direct audio earns its extra operational complexity when interruption handling, vocal cues, and shorter conversational pauses matter enough to justify parallel transcription and richer event logging.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.