A Chatbot Denial Needs a Reason Code, Not More Words
A fluent explanation is useless if it cannot be traced to the rule that produced a denial. Reason codes make chatbot language reviewable before it reaches a customer.
October 4, 2026 · 8 min read
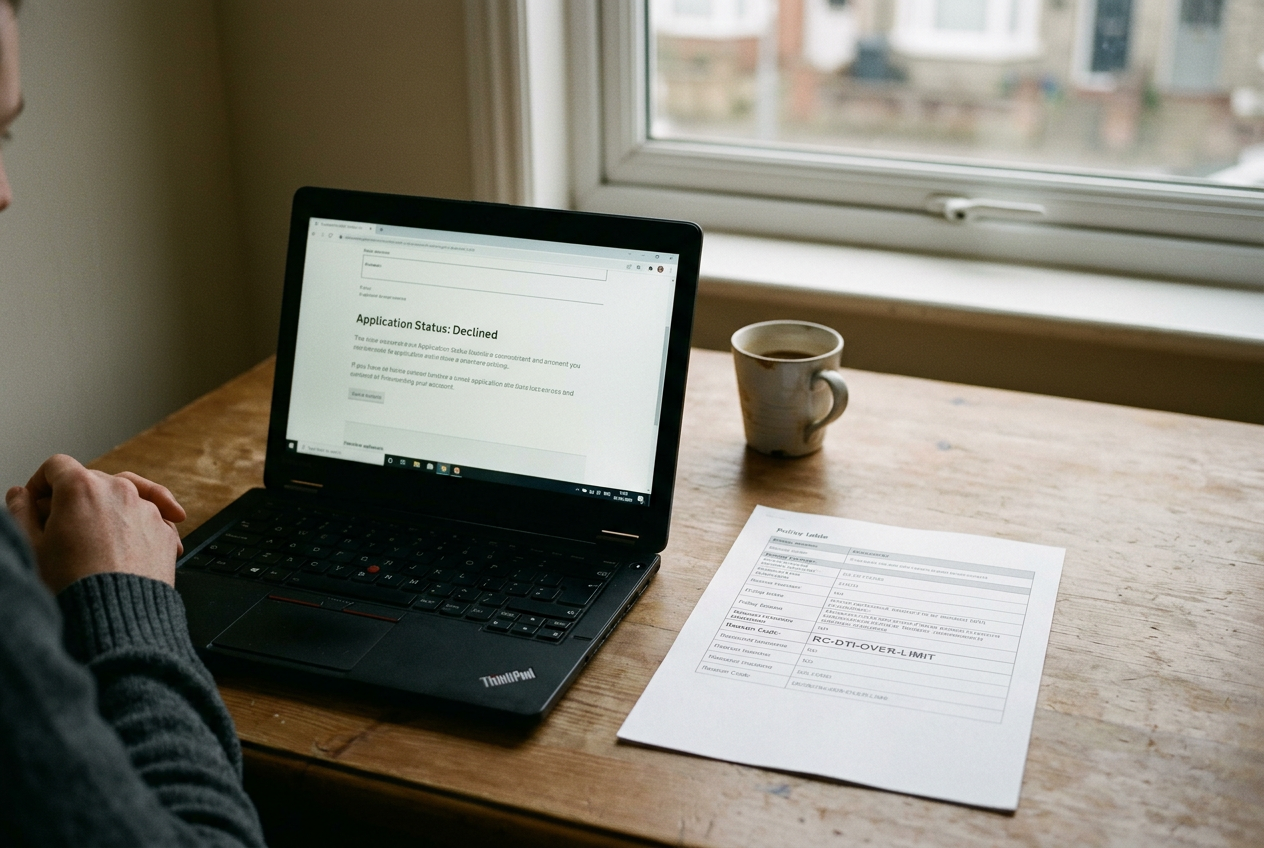
Consider an online credit application that ends inside a customer-service chatbot. The decision system declines the application because verified monthly debt exceeds the product’s approved debt-to-income ceiling, but the chatbot receives only `status: denied`. Asked to explain, a language model produces a plausible sentence about credit history, income, or eligibility.
That sentence may sound helpful. It is also disconnected from the decision.
The missing object is a code such as `RC-DTI-OVER-LIMIT`, emitted by the system that applied the lending rule. The code does not need to be shown to the applicant. It needs to travel with the result, point to the rule and policy version that generated it, and limit what the chatbot can say.
This matters beyond customer experience. In regulated decisions, an organization may need to show why an adverse action, meaning a denial or another unfavorable credit decision, occurred for that applicant. A paragraph invented after the event is not reliable evidence, even when it happens to name a factor that appeared somewhere in the application.
The code belongs where the decision happens
A reviewable workflow separates the decision from its presentation. First, an application service validates the submitted data and records which values came from the applicant or another permitted source. A rules engine or scoring system then applies the current product policy. When that system returns a denial, it also returns one or more reason codes representing the principal reasons that produced the result.
Only then does the chatbot speak.
For the example application, the decision response might contain the denial status, `RC-DTI-OVER-LIMIT`, the policy version, and an identifier for the underlying decision record. A controlled mapping table connects that code to the relevant policy clause and to approved customer language, such as a statement that the applicant’s monthly debt obligations were too high relative to verified income for this product.
The chatbot may adjust tone or sentence structure if the organization permits generated language, but it cannot substitute a different reason. It should not infer that a low score caused the denial, mention a late payment because one appears in the file, or combine several possible explanations into a polished guess.
A reason code is therefore a join key, an identifier used to connect records across systems. It joins the customer message to the decision output, the active policy, and the audit log. That connection is more valuable than a longer explanation because a reviewer can follow it backward.
Specific reasons are already an enforceable requirement in credit
For US creditors covered by the Equal Credit Opportunity Act and Regulation B, specificity is not a proposed AI principle. Regulation B states:
“The statement of reasons for adverse action required by paragraph (a)(2)(i) of this section must be specific and indicate the principal reason(s) for the adverse action. Statements that the adverse action was based on the creditor’s internal standards or policies or that the applicant, joint applicant, or similar party failed to achieve a qualifying score on the creditor’s credit scoring system are insufficient.”
That language appears in 12 CFR §1002.9(b)(2). The Consumer Financial Protection Bureau has also said that creditors do not escape adverse-action notice requirements because they use complex algorithms whose operation is difficult to describe.
A reason-code architecture does not by itself establish compliance. A vague code such as `INTERNAL_POLICY` merely stores the kind of explanation the regulation calls insufficient. Nor can a team maintain a generic list of possible reasons and select whichever one sounds most understandable after the decision. The code has to reflect the principal reason produced in the individual case.
Outside regulated credit decisions, there is no universal US rule requiring every chatbot refusal to carry a reason code. A retailer declining a return and a bank denying credit do not operate under identical notice duties. Some organizations still adopt the pattern for insurance, account restrictions, marketplace moderation, or benefit administration because it improves internal review, but that design choice should not be presented as a legal mandate that applies everywhere.
Generation comes after the evidence
Teams often reverse the order. They send a model the customer’s record, the denial status, and a prompt asking for a concise explanation. This may produce readable text, yet the model must reconstruct causality from nearby facts rather than receive the cause from the system that made the decision.
The safer sequence is narrower. The decision service emits the reason code. A policy registry resolves that code to approved meaning and any disclosure constraints. A template or constrained generation step produces the customer-facing sentence from that approved material, while the chatbot handles follow-up questions using the same code rather than reconsidering the application.
For `RC-DTI-OVER-LIMIT`, the model could be allowed to explain what debt-to-income means in plain language, provided it does not expose restricted data or promise that changing one input guarantees approval. If the customer asks whether a specific credit-card balance caused the denial, the bot should answer only when the decision record supports that level of detail. Otherwise, it should route the request to the organization’s established review channel.
This setup uses less model freedom. That is the point. Fluency remains useful at the presentation layer, where wording may need to fit chat, email, or a formal notice, but the model receives no authority to determine the reason.
Templates are a credible alternative. For a small and stable reason taxonomy, fixed text costs less to test and creates fewer opportunities for drift. Generation becomes worthwhile when explanations need controlled variation across reading levels, channels, or supported languages, although every added variation increases evaluation work and the chance that wording changes the meaning.
The log must preserve the decision-time state
A reviewer examining the sample denial should be able to retrieve the inputs used by the decision system, the output status, `RC-DTI-OVER-LIMIT`, and the version of the policy mapping that was active at that moment. The record should also preserve the exact customer-facing text and whether a template, model, or human produced it.
Policy versioning matters because mappings change. If the product later changes its debt-to-income ceiling or rewrites the approved explanation, an auditor cannot evaluate an older denial against the current table. The historical record must point to the rule and language available when the result was issued.
Model logs alone do not meet that need. A prompt and response can show what the chatbot said, but they do not prove that the stated reason caused the decision. Conversely, a decision log without the delivered text cannot show whether the chatbot contradicted the code or added unsupported claims. Reviewability requires the link between them.
Storing that link has a privacy cost. Decision inputs and generated messages may contain sensitive financial information, so access controls and retention rules should cover the joined record rather than treating chatbot logs as harmless conversation data. The useful audit artifact is not an unrestricted transcript. It is a controlled record with enough evidence to reconstruct the result.
Taxonomy design is the hard part
The main expense appears before runtime. Policy, compliance, product, and engineering teams have to agree on codes that are specific enough to explain outcomes without becoming an unmaintainable copy of every rule branch. They must decide how to rank multiple contributing reasons, handle missing or conflicting data, and retire codes without breaking historical records.
Codes also fail when they describe model features instead of decision reasons. A scoring model may use many inputs, but a feature with high statistical influence across the model is not automatically the principal reason for one applicant’s denial. Any method that converts model behavior into an adverse-action reason needs testing against the decision logic and the applicable notice standard; attaching a generic feature-importance tool after deployment does not settle that question.
The fallback should be explicit. If the decision system returns a denial without a recognized code, the chatbot should not improvise. It can acknowledge that the application was not approved and transfer the case to a controlled review path, while the missing code triggers an operational alert. That creates friction and may delay an answer, but it exposes a broken interface rather than hiding it behind fluent text.
The same rule applies when the code and available data conflict. In the sample workflow, `RC-DTI-OVER-LIMIT` should not survive if the decision record lacks the verified income and debt values needed to apply that rule. The system should flag the record for investigation instead of asking the chatbot to smooth over the inconsistency.
A practical acceptance test
Before connecting a chatbot to adverse results, take one real decision from a test environment and trace it in reverse. Start with the exact sentence the customer would receive. Locate the reason code, then the versioned policy mapping and the decision output that emitted it. Confirm that the underlying record supports the reason and that changing the policy version does not rewrite the historical explanation.
Next, remove the code. The chatbot should stop and invoke the documented fallback. If it still generates a rationale, the architecture is allowing language generation to replace decision evidence.
That test is more useful than asking reviewers whether an explanation sounds clear. Clarity matters after provenance, meaning the recorded origin and history of the explanation, has been established. Without provenance, better prose only makes an unsupported rationale easier to trust.
Questions people ask
Can a reason code be shown directly to the customer?
It can, but an internal identifier such as `RC-DTI-OVER-LIMIT` is rarely sufficient customer language. The organization should map the code to a specific plain-language statement while preserving the identifier in the decision record, so support staff and reviewers can trace the statement without forcing the customer to interpret system terminology.
Can a language model choose the reason code?
A model should not choose among plausible codes after receiving only a denial and the application file. The decision system should emit the code as part of its result. If a model participates in the decision itself, the organization still needs a tested method for producing principal reasons tied to that individual outcome.
Are reason codes required for every chatbot denial?
No universal US requirement covers every chatbot refusal. Credit adverse actions carry specific obligations under laws including the Equal Credit Opportunity Act and Regulation B, while other domains have different rules. Teams may still use reason codes voluntarily because they make denials easier to review, test, and correct.
What should happen when the system returns no reason code?
The chatbot should use a limited fallback and route the case through the organization’s established review process rather than inventing an explanation. The missing code should also create an operational alert, preserving the denial response and decision identifier so engineers can find the broken rule mapping.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.