A Data-Access Request Can Reach Your AI’s Hidden Scores
Prompts and profile fields may be only part of the record. AI-generated labels, rankings, and summaries can also relate to a person and may need to be found, reviewed, and disclosed.
September 23, 2026 · 8 min read
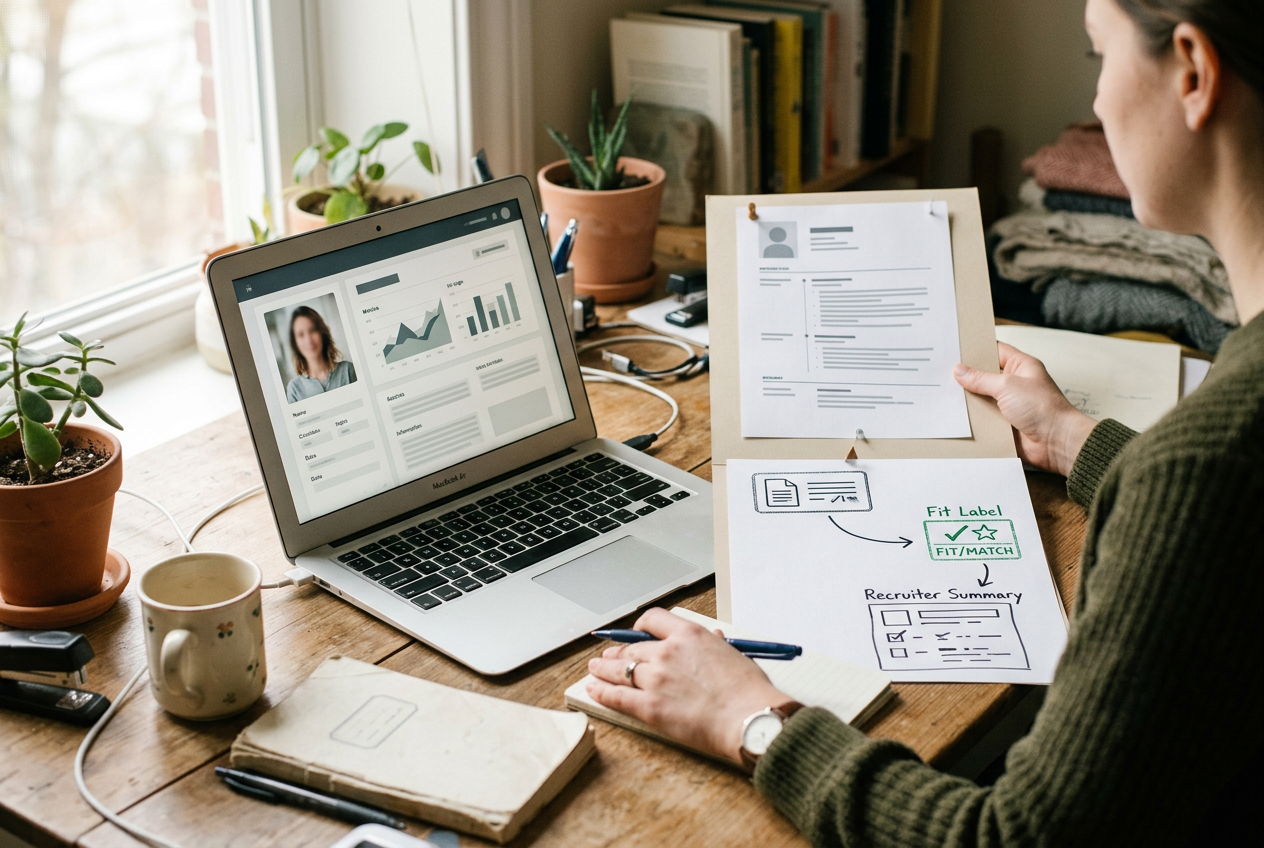
Consider a hiring platform that receives an applicant’s résumé, converts it into structured fields, sends selected text to a language model, and writes two outputs back to the applicant tracking system: “customer support fit: high” and a recruiter-facing summary. The applicant later submits a data-access request.
Exporting the account profile and original résumé would miss the system’s most consequential records. The fit label may live in a feature store, which holds model-ready variables; the summary may sit in a recruiter note; an earlier score may remain in an evaluation log. Each record can affect how the applicant is viewed even though the applicant never supplied it.
This is where a routine privacy workflow becomes a systems problem. Legal counsel must identify the governing right and its limits, while engineering must establish where derived data traveled, which copies still exist, and whether the company can connect them reliably to the requester. This explainer is a practical map, not legal advice.
Start with the output, not the prompt
A useful first step is to reconstruct one completed run of the hiring workflow. Start with the final recruiter screen and move backward through every write operation, rather than searching only databases labeled “user data.”
In the example, a résumé parser first extracts employment dates and skills. A rules service removes applicants who lack a required certification. The remaining text goes to a model, which produces a summary and fit label. A ranking service combines that label with other variables, then the applicant tracking system displays the result to a recruiter.
The request search should follow that same path. It may reach the applicant tracking system, model gateway logs, prompt and response history, feature store, ranking table, analytics warehouse, recruiter notes, monitoring samples, and support tickets created after the applicant challenged the result. A vector database, which stores numerical representations used for similarity search, may also contain an embedding tied to the applicant or document.
Do not assume every artifact must be returned. A model’s internal weights are not ordinarily a requester-specific record, and infrastructure telemetry may contain no information that relates to the person. The technical team’s job is to locate and characterize the material. Counsel decides how the applicable law treats it.
Treat an inference as data with a lineage
An inference is a conclusion produced from other information, such as a fit label derived from résumé text. Its lineage records the inputs, transformations, model or ruleset, timestamp, destination, and later use that produced the output.
For the “customer support fit: high” label, the lineage should show which applicant record was processed, whether the system used the current résumé or an older version, where the label was stored, and whether a recruiter changed it. Without that chain, a company may disclose the final label but be unable to tell whether it belongs to the requester, whether it was superseded, or whether it influenced a decision.
Identity joins deserve special attention. Production systems often connect records through an applicant ID, email hash, document ID, session ID, or vendor-specific identifier rather than a name. A privacy search that checks only an email address can therefore return a clean result while the ranking table still holds the person’s score under an internal key.
Build a request-specific data map from the actual workflow, not the architecture diagram. For each system that read or wrote applicant information, record the identifier used, the derived fields created, retention status, system owner, export method, and downstream recipients. This takes engineering time, particularly when a vendor exposes only a dashboard or support-mediated export, but it is less risky than asking each team whether it stores “personal data” and receiving incompatible interpretations.
Apply the legal test to each located record
Under the EU General Data Protection Regulation, personal data means “any information relating to an identified or identifiable natural person.” Article 15(3) then states: “The controller shall provide a copy of the personal data undergoing processing.” An AI output can fall within that broad definition when it evaluates, describes, or is used to make a decision about an identifiable applicant.
The requirement is not limited to facts supplied by the person. A generated summary may contain opinions, predictions, or errors and still relate to the applicant. In its CRIF judgment, case C-487/21, the Court of Justice of the European Union said the copy must give the data subject a faithful and intelligible reproduction of the personal data undergoing processing. That does not automatically require handing over every source document or complete database row; context may be needed when it is essential to make the personal data intelligible.
Automated decision-making creates a separate issue. Article 15(1)(h) covers “meaningful information about the logic involved” and the significance and envisaged consequences in the automated decision-making cases referenced by Article 22. The SCHUFA judgment, case C-634/21, also established that producing a probability score can qualify as an automated individual decision when a third party gives that score a determining role. Whether the hiring workflow meets that test depends on how the score was used, including whether human review had real authority rather than serving as a nominal checkpoint.
California’s Consumer Privacy Act expressly includes certain inferences within personal information. California Civil Code section 1798.140 describes “inferences drawn from any of the information identified in this subdivision to create a profile about a consumer reflecting the consumer’s preferences, characteristics, psychological trends, predispositions, behavior, attitudes, intelligence, abilities, and aptitudes.” A hiring fit label may warrant analysis under that language, though coverage, employment-related applicability, exemptions, and response obligations require case-specific review.
These are enforceable statutory rights and court interpretations, not general AI ethics principles. A company policy promising broader explainability may create an operational commitment, but it does not change the text of the access right. Conversely, a product team’s proposed transparency feature does not satisfy an enforced request until it returns the records and information the applicable rule requires.
Separate access from explanation
Teams often merge three different tasks: supplying personal data, explaining an automated decision, and exposing intellectual property. That produces two predictable errors. One response contains only a generic model description, while another dumps raw logs that the requester cannot connect to the hiring outcome.
For the example workflow, an intelligible package might identify the fit label, generated summary, relevant structured résumé fields, creation dates, corrections, and the systems or recipients to which the outputs were sent. If automated-decision provisions apply, counsel may also require information explaining the principal factors and how the score affected the process. The exact content depends on the governing law and facts.
Source code and model weights are a different category from requester-specific outputs. GDPR Recital 63 recognizes the rights and freedoms of others, including trade secrets and intellectual property, but says those considerations “should not result in a refusal to provide all information to the data subject.” That calls for scoped review and redaction where justified, rather than using vendor confidentiality as a blanket answer.
Raw prompt logs need similar handling because one entry may contain another applicant’s résumé, recruiter instructions, or security information. Preserve the requester’s data and enough context to make it understandable, then assess third-party information and protected material separately. Redaction adds review time; an unfiltered log export can create a new privacy incident.
Verify the response against the live system
Before sending the package, replay the data map against the applicant’s identifiers. Confirm that the disclosed “high” label matches the value shown to the recruiter, that prior values are accounted for under the applicable retention and access rules, and that a vendor did not keep another copy under a document or tenant ID.
Then compare the response with the system’s user interface. If the recruiter screen shows an AI summary that the export omits, the discrepancy needs an explanation or another search. If the export includes a score with no date, scale, or purpose, the requester may receive the bytes without receiving an intelligible account of what the record means.
Backups require a documented position rather than an improvised promise. Some backup stores cannot retrieve one person’s record without restoring a larger dataset, while deleted production data may remain until scheduled rotation. Counsel should assess the applicable obligation, and engineering should describe the technical state accurately, including whether the record is active, isolated, inaccessible in ordinary operations, or scheduled for deletion.
Finally, preserve receipts: the request date, identity-verification steps, systems searched, query terms and identifiers, vendor responses, exclusions, redactions, approver, and delivery record. Those receipts do not prove that every legal judgment was correct. They do show what the organization checked, which is indispensable when the visible applicant record and the hidden model output disagree.
Questions people ask
Does a data-access request always include an AI score?
No. Coverage depends on the jurisdiction, the organization’s role, the requester’s relationship to it, and whether the score relates to an identifiable person. The safe operational approach is to locate the score and document its use before counsel decides whether it must be disclosed or may be withheld.
Do we have to provide the model’s source code or weights?
Usually, a request for personal data is not automatically a demand for source code or full model weights. The response may still need to include requester-specific outputs and meaningful contextual information, while counsel assesses intellectual property, trade secrets, third-party rights, and any automated-decision requirements.
Is a generated summary covered if it is wrong?
Potentially. Accuracy is not the threshold for deciding whether information relates to a person; an incorrect summary can still describe that person and affect a decision. The response workflow should preserve the original record, mark later corrections, and route any rectification request through the applicable process.
What should we ask an AI vendor to export?
Ask for records linked to all known identifiers, including prompts, outputs, scores, embeddings where relevant, moderation results, evaluation samples, timestamps, model or ruleset references, and downstream destinations. The contract and technical interface should also state retention periods, deletion behavior, subprocessor access, and how the vendor supports statutory response deadlines.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.