Data Access Requests Cannot Stop at the Vector Database
AI systems scatter personal information across source files, prompts, embeddings, caches and summaries. A defensible access workflow must trace those copies without pretending every vector is a readable record.
October 28, 2026 · 8 min read
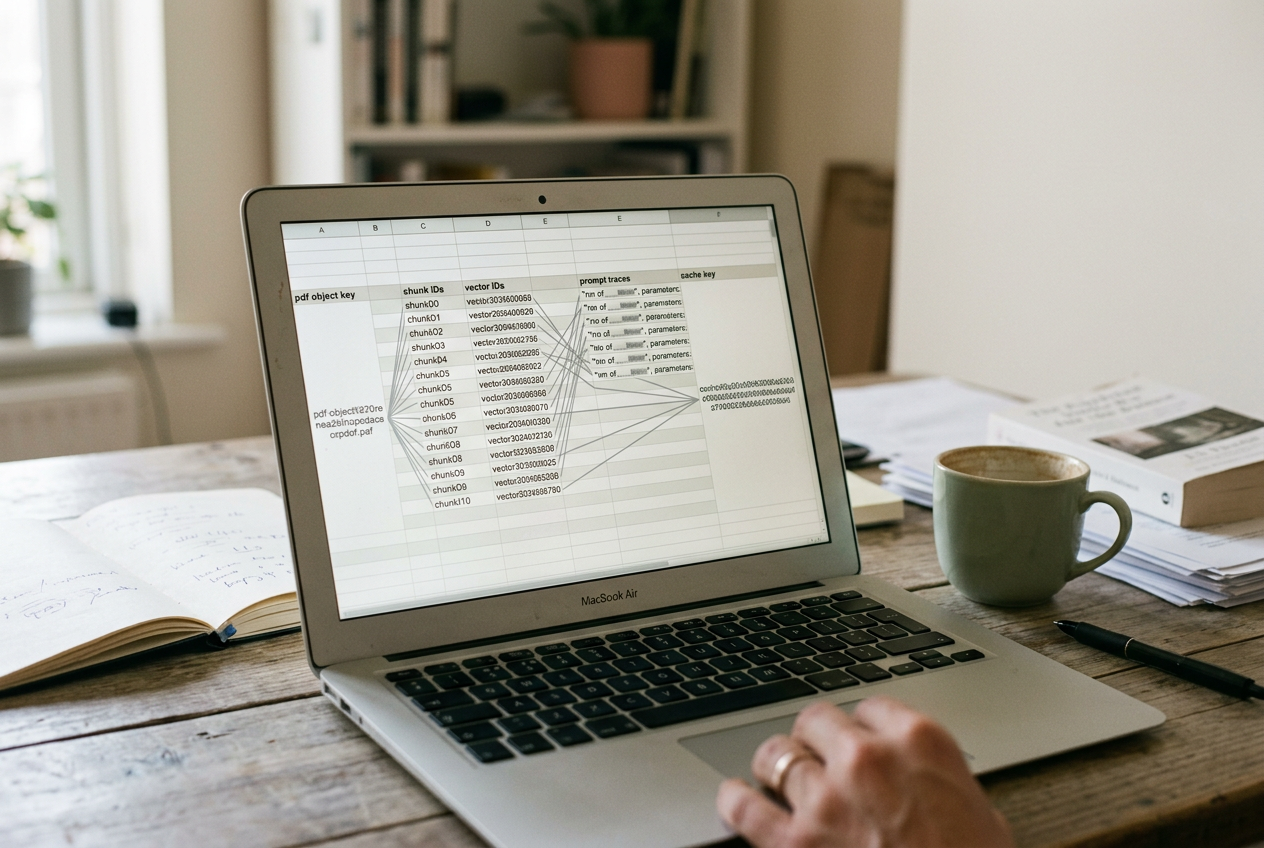
Consider one request moving through a benefits support assistant. A user uploaded an accommodation letter as a PDF, the system extracted its text, divided that text into passages and converted each passage into an embedding, which is a numeric representation used to find semantically similar content. The assistant later retrieved two passages, placed them in a model prompt and cached a generated summary for the support team.
Weeks later, the user asks for a copy of their personal information and correction of an outdated restriction described in the letter. The privacy team finds the original PDF in object storage and closes its search.
That is the failure to avoid.
The same restriction may now appear in extracted text, a prompt log, retrieved context, a support note and the generated summary. The vector database may hold an embedding linked to the document identifier even though the vector itself does not display a name or sentence. A response workflow that searches only the customer database misses the stores built specifically so the AI system can recall and reuse information.
This is not a new, vector-specific legal right. It is an architecture problem inside existing access, correction and deletion duties, where those duties apply. The practical change is that a data map describing “documents” or “support records” no longer tells an operator where all usable copies reside.
The requirement applies to data, not familiar file types
Under the EU General Data Protection Regulation, Article 15(3) says a controller “shall provide a copy of the personal data undergoing processing.” Article 12 requires that communications about data-subject rights use a “concise, transparent, intelligible and easily accessible form, using clear and plain language.” Those are existing requirements, although their application to a particular embedding depends on the facts.
California law gives a consumer the right to request the “specific pieces of personal information” a business has collected about that consumer, subject to the law’s scope and exceptions. Its definition of personal information also includes certain inferences used to create a profile. Other jurisdictions set different thresholds, exemptions and response rules.
None of those provisions says that every floating-point number in a vector index must be printed into an access package. They also do not let an organization exclude a store merely because its contents are machine-oriented. The relevant analysis starts with whether information relates to an identifiable person and how the organization can connect, retrieve or use it, not whether a human can read the storage format unaided.
That distinction matters in the accommodation-letter case. An embedding with no durable link to a person, no recoverable source and no realistic path back to an individual may fall outside a search result after a documented assessment. An embedding stored beside a user ID, document ID and source passage is different: the surrounding system can locate and use it precisely because of those links.
Start with the retrieval path
The fastest map usually follows the assistant’s retrieval path rather than the organization chart. Begin with the identifier available from the request, such as an account ID, email address or case number, then inspect where the application resolves that identifier into documents and derived records.
For the benefits assistant, the original upload has an object key. An ingestion job records that key while producing extracted text and smaller passages, often called chunks. Each chunk receives its own identifier before an embedding service converts the text into a vector and writes it to an index with metadata. A retrieval service searches that index, sends selected chunks into a prompt and may preserve the resulting prompt, model output, trace or cache entry elsewhere.
The useful artifact is a lineage table linking the request identity to the source document, chunk IDs, vector IDs, prompt or trace IDs, cache keys and downstream support record. It does not need to duplicate the content. It needs to show where the content went, which transformation produced each copy, how long that copy remains and what deletion or correction operation reaches it.
Search by both identity and lineage. A vector record may not contain the user’s email, while its metadata contains only a chunk ID that points to an ingestion table. Prompt logs can reverse the pattern by preserving copied text without the source identifier. Generated summaries may have been written into a ticketing system under an employee-facing case number.
Exact-name searches miss all of these arrangements.
This mapping adds operational cost. Engineers may need to query production stores, archived logs and vendor systems, while broad searches can expose unrelated users’ information to the response team. A better setup records lineage during ingestion and retrieval, applies access controls to the lookup tool and returns references before it returns content. That turns the accommodation-letter request into a bounded trace instead of a manual search across every AI service.
A raw embedding is rarely an intelligible answer
An embedding is usually an array of numbers whose meaning depends on the model and indexing setup that produced it. Handing that array to the requester may be technically possible, but it generally does not reveal the underlying statement in an intelligible way. It can also create a false impression that the organization has supplied useful access merely because it exported every stored field.
The response team should separate discovery from delivery. Use the vector record and its metadata to locate the associated person, source passage and downstream uses. Then return the personal information in a form the requester can understand, along with relevant contextual information required by the governing regime, while recording the decision about whether the vector itself belongs in the package.
That decision should not rest on the phrase “proprietary format.” The team should document whether the vector is linked to the requester, whether it can be used to infer or retrieve information about them, whether a raw export would communicate anything meaningful and whether disclosing it could affect other people’s rights or protected system information. Legal and privacy review may reach different conclusions across systems and jurisdictions.
There is no broad enacted rule that establishes one universal export format for embeddings. General access requirements are enforceable where applicable; architecture-specific treatment remains dependent on context, regulator guidance and future decisions. A policy promising either “all vectors are always personal data” or “embeddings are never personal data” is therefore brittle.
Correction means rebuilding derivatives
The user in the benefits case also wants an outdated restriction corrected. Editing coordinates inside the embedding is not a meaningful repair because individual dimensions do not correspond to editable words. The reliable sequence changes the authoritative source or records the corrected source, reruns text extraction and chunking, creates replacement embeddings, and removes or retires the old chunks and vectors.
The work continues downstream. A cached summary can preserve the outdated restriction after the index has been rebuilt, while an old prompt log may remain under a separate retention rule. Search indexes can lag behind their primary stores, backups may not permit immediate record-level deletion and external model providers may have their own retention arrangements. The response owner must distinguish an active production copy from a restricted archive rather than reporting that every byte vanished at once.
Deletion follows the same lineage but may produce a different outcome because legal obligations, security needs or another exception can permit retention. Where deletion applies, remove the source and active derivatives, invalidate retrieval and response caches, and prevent a scheduled ingestion job from recreating the vector from an untouched replica. If a backup cannot be edited immediately, record when it expires and ensure restored data reenters the deletion workflow before serving traffic.
For the accommodation letter, the completion check is behavioral: a search using the old passage’s terms should no longer retrieve the retired chunk, and the support interface should display the corrected record. That test is stronger than a successful database command because it checks the path that exposed the information in the first place.
Keep receipts for the response
A defensible request file records the stores searched, identifiers used, lineage discovered, exports produced, transformations rerun and exceptions applied. Preserve query results or signed job receipts where appropriate, but do not copy sensitive content into a new compliance log just to prove that it existed.
Ownership also needs to be explicit. The privacy team can define the request scope, yet engineering must expose stable lookup and deletion operations, while system owners must confirm that ticketing tools, analytics stores and vendors received the action. If nobody owns the vector index because it is treated as replaceable infrastructure, the access workflow will fail at the same point as the first search.
The immediate engineering task is modest: take one real request identifier, trace it through the benefits assistant from upload to retrieval, and note every point where the identifier changes. The missing link in that trace is the next control to build.
Questions people ask
Do
I have to give someone their raw embedding?
Not automatically in every jurisdiction or system. Assess whether the embedding is personal data in context, whether it is linked to the requester and what form makes the information intelligible; document the reasoning rather than excluding vectors by policy or exporting unusable numbers by default.
Can an embedding reveal the original text?
An embedding is not normally a reversible copy of a sentence, but that does not make it anonymous. Its metadata, neighboring records and use in retrieval can connect it to a person or source passage, and technical attacks or comparison datasets may reveal information depending on the setup.
How do
I correct personal information stored in a vector database?
Correct the authoritative source, regenerate its chunks and embeddings, retire the prior vector records, and invalidate caches or summaries that preserve the error. Do not try to edit individual vector dimensions as if they were fields in a customer profile.
Are backups and prompt logs part of the search?
They can be, depending on the applicable law, system design, retention purpose and available exceptions. Record whether they are searchable or active, restrict retained copies, and make sure restored backups reapply completed corrections or deletions before the data returns to production.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.