Your Hiring Tool’s Bias Audit May Cover the Wrong System
Selection-rate testing can reveal disparities in one hiring workflow. It cannot certify accuracy, fairness or compliance when the software, applicant pool or deployment has changed.
September 15, 2026 · 8 min read
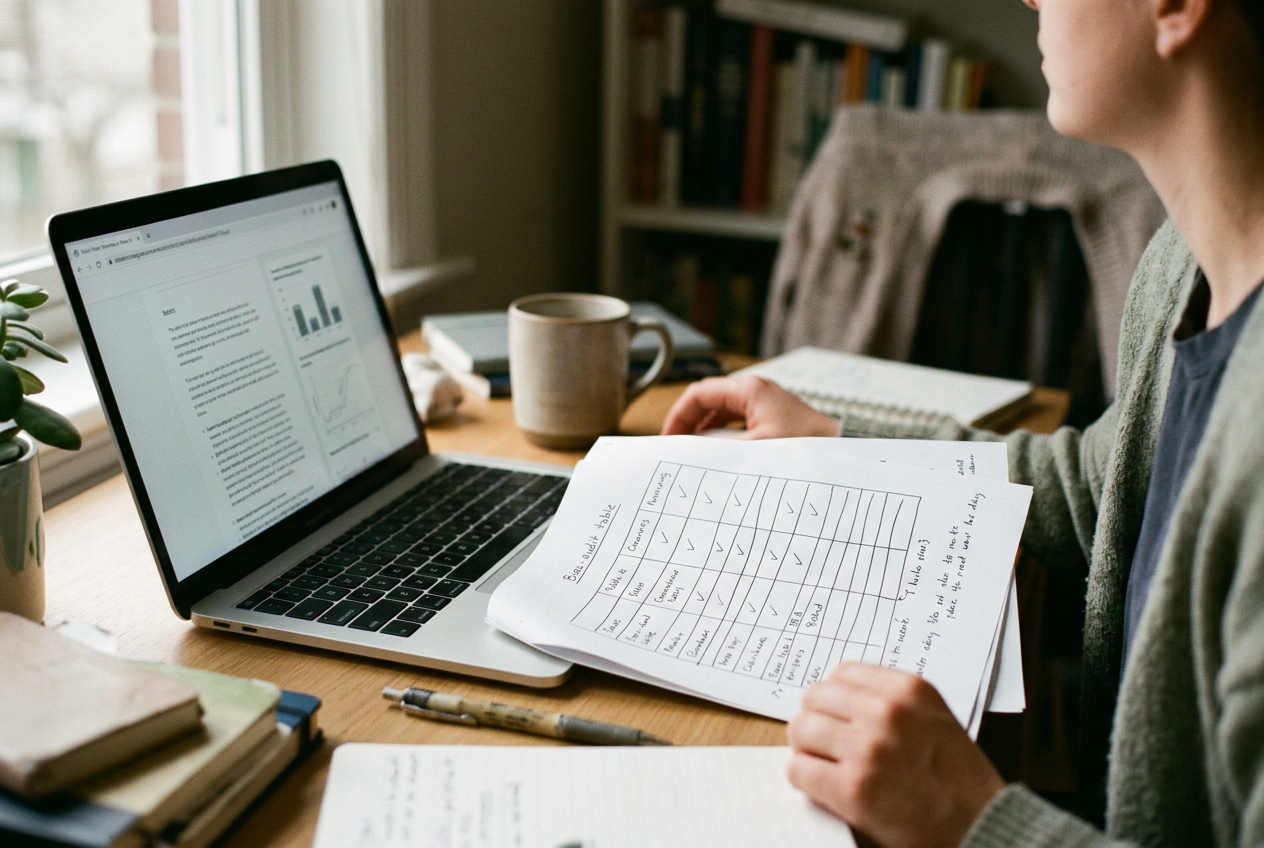
The useful object is not the certificate-shaped cover page. It is the audit table showing who entered a hiring stage, who the automated employment decision tool recommended or advanced, and whether selection rates differed across demographic groups.
Imagine that table attached to a procurement ticket for a resume-ranking system. The vendor says its product has undergone an independent bias audit. Your team plans to use the system to rank applicants for engineering and customer-support roles, with recruiters reviewing only candidates above a configured threshold.
The audit report, however, covers an earlier software build, pools several job families, and tests recommendations before any customer-specific threshold is applied. It may be a legitimate audit of what it examined. It is weak evidence about the workflow you intend to run.
That distinction matters because selection-rate testing answers a bounded question: given the people in the audit data and the decision rule tested, how often did each group receive the favorable outcome? It does not establish that the model chose qualified people, used lawful features, resisted manipulation, protected applicant data or behaved consistently after deployment.
What the audit calculation establishes
A selection rate is the share of a demographic group that receives a favorable result. If 200 applicants from a group enter the measured stage and 40 advance, that group’s selection rate is 20 percent. The impact ratio compares that rate with the rate for the most-selected group.
The federal Uniform Guidelines on Employee Selection Procedures describe the commonly cited four-fifths test this way: “A selection rate for any race, sex, or ethnic group which is less than four-fifths (4/5) (or eighty percent) of the rate for the group with the highest rate will generally be regarded by the Federal enforcement agencies as evidence of adverse impact.” The same sentence says a rate above four-fifths generally will not be regarded as evidence of adverse impact.
“Generally” carries real weight. The guidelines also recognize that smaller differences may be significant and that an apparent disparity based on small numbers may not be reliable. Four-fifths is a screening convention, not a mathematical boundary between lawful and unlawful systems, and passing it does not create a safe harbor.
New York City’s Local Law 144 makes this calculation operational for certain employers and employment agencies using an automated employment decision tool, or AEDT, on candidates or employees in the city. The law defines a bias audit as “an impartial evaluation by an independent auditor” that includes testing for disparate impact based on specified sex, race and ethnicity categories. City rules prescribe calculations and require a public summary of results before covered use, alongside notice obligations.
The enforced requirement is narrower than the claim often made in sales material. Covered users must arrange the required audit and disclosures for a covered AEDT. The law does not declare that an audited tool is fair, safe, accurate or suitable for every hiring decision.
The resume-ranking audit table can therefore establish that, for its recorded population and favorable-outcome definition, one group advanced at a particular rate relative to another. That is useful. It may expose a threshold that sharply changes group outcomes, a job family with a larger disparity or a data gap that prevents a credible calculation.
It cannot explain the disparity by itself. The cause could sit in the model, its training labels, the threshold, the applicant pool, missing demographic records, recruiter overrides or an earlier stage that shaped who reached the tool. Selection-rate analysis observes an outcome pattern; it does not isolate causation.
The audited version must be the deployed version
Software identity is the first procurement check. Ask for the product name, model or ruleset identifier, release information, audit date and a record of material configuration choices. A report for a generic service is not enough when the deployed ranking depends on customer-selected features, knockout questions, score weights or thresholds.
Return to the resume-ranking workflow. The base system assigns applicants a score, but the employer decides that only candidates above a threshold appear in the recruiter queue. If the auditor studied the score distribution without applying that threshold, while the employer’s threshold determines who receives review, the tested outcome does not match the operational decision.
Updates create the same problem. A vendor may change the underlying model, parsing logic, occupational taxonomy or treatment of missing resume fields without changing the product name visible to buyers. The relevant question is whether the change could alter rankings or selection outcomes. If it could, an older audit may no longer describe the deployed tool, even if the report remains within a permitted use period.
Buyers should also request a change log and a contractual trigger for review after material changes. That adds cost and slows upgrades, but the alternative is to keep presenting a historical result as evidence about software that no longer exists in the tested form.
Population and job grouping can change the result
An impact ratio depends on its denominator and comparison group. Pooling applicants for unrelated jobs can conceal a disparity that appears within one job family, particularly when demographic composition and hiring volume differ across roles.
Suppose the audit combines engineering, sales and support applications, while your deployment covers support roles only. The combined table may be arithmetically correct yet offer little evidence about support hiring, because each occupation can attract a different applicant population and use a different decision threshold. A buyer needs the job categories included, the locations covered, the audit period and the rules used to combine or exclude records.
Historical data can be informative when it reflects the tool’s real use. It can also preserve old recruiting channels, prior job requirements and human decisions that no longer apply. Test data avoids some recordkeeping gaps but introduces another constraint: synthetic or constructed applicants may not reproduce the resume formats, career histories and missing fields found in production.
Demographic data quality deserves its own line in the review. Auditors need group information to calculate selection rates, yet employers may store voluntary self-identification separately from application records, have substantial nonresponse or rely on data assembled for another reporting purpose. The report should state its data source, exclusions and missingness rather than turning an incomplete population into a clean-looking ratio.
Small groups require caution. A single additional selection can move a rate sharply when only a few people are represented, while a large pooled sample can produce a stable aggregate that hides variation by job. Neither problem is fixed by quoting the impact ratio to more decimal places.
The decision point must match the real workflow
A hiring pipeline contains several decisions: an application may be rejected by a knockout rule, ranked by a model, placed in a recruiter queue, selected for interview and eventually offered a job. An audit of one point does not automatically cover the others.
For the resume-ranking system, write the workflow in order. First, the application form enforces minimum requirements. Next, the tool parses the resume and produces a score. The configured threshold controls entry to the recruiter queue.
Recruiters can then advance, reject or search for candidates outside that queue.
The favorable outcome in the audit must map to one of those events. “Recommended” is not interchangeable with “interviewed,” and a score above a threshold is not the same as a job offer. If human reviewers frequently override the ranking, the model-output audit and the end-to-end hiring outcome answer different questions; both may matter, but neither substitutes for the other.
Logging is the practical constraint. To reproduce selection-rate testing, the employer needs records of who entered the stage, the tool output they received, the configuration active at that time and the resulting decision. Without those receipts, a later audit may reconstruct only part of the workflow, and neither the buyer nor the auditor can tell whether a disparity arose before or after the automated recommendation.
Read the report as a scope document
Before approving the procurement ticket, compare the report with a one-page deployment record. That record should identify the software build and configuration, covered jobs and locations, applicant-data period, measured decision point, favorable outcome, demographic-data source, exclusions and human override path. These are not decorative audit details. They define what the result means.
Then separate claims. “An independent auditor calculated selection rates for this configuration and population” may be supported. “The tool is unbiased” is not. Claims about job-related validity, accessibility, privacy, security and explainability require different evidence, while legal compliance depends on the employer’s use and obligations rather than the existence of a vendor document.
Independence also needs examination. New York City’s rules set conditions intended to keep the auditor from participating in the tool’s development or use and from holding a disqualifying financial interest. Buyers should identify who performed the work, who supplied and cleaned the data, and whether the auditor could reproduce the tested configuration. Paying for an audit does not by itself invalidate it; calling a vendor’s internal assessment independent may.
A mismatch does not always require abandoning the tool. The fallback may be a deployment-specific audit, a narrower rollout with preserved human review, removal of a customer-set threshold or better event logging before the system influences decisions. Each option costs time and money. None can be replaced by putting the old audit PDF into the compliance folder.
Questions people ask
Does passing the four-fifths test prove a hiring tool is unbiased?
No. The test flags certain selection-rate differences in a defined dataset, and the federal guidelines describe it as a general rule rather than a safe harbor. It does not test whether the model is accurate, job-related, accessible, privacy-preserving or free from disparities at another hiring stage.
Can a vendor’s bias audit cover every customer?
Only when the audited setup meaningfully matches each customer’s use. Customer-specific thresholds, knockout rules, job populations and integrations can change who receives a favorable outcome. A generic audit may still provide background evidence, but buyers need deployment-level documentation before treating its ratios as representative.
What should I request with a hiring-tool bias audit?
Request the tested software and configuration, audit period, job and location scope, data source, exclusions, group counts, selection rates, impact ratios and favorable-outcome definition. Also obtain the change log and workflow documentation showing where the tool’s output affects a recruiter or hiring decision.
Does an independent audit transfer compliance responsibility to the auditor?
No. An auditor evaluates the scoped system and data, while the employer or employment agency controls deployment, notices, workflow configuration and recordkeeping. The exact obligations vary by jurisdiction and use, so the report should be treated as evidence for a defined test rather than a general compliance certificate.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.