An AI Copyright Opt-Out Needs More Than a Submission Receipt
A form can record a creator’s objection without proving that any work was excluded. A useful opt-out needs asset-level scope, run-level status and a path to challenge errors.
October 30, 2026 · 8 min read
Use a twelve-URL request as the acceptance test. A photographer submits twelve pages containing licensed images, receives an email saying the request was accepted, and later needs to establish whether the system recognized every URL, matched the underlying files and excluded them from a future model run.
Many opt-out workflows stop before answering those points. The form acknowledges an event, much as a support ticket does, but it may not return the normalized URLs, content hashes, applicable models, cutoff date or final disposition of each item. The creator cannot tell whether “accepted” means received, identity-verified, matched to training data or placed on an exclusion list.
That uncertainty is technically avoidable. It also matters more than the presence of a polished submission page.
A receipt proves that a form worked
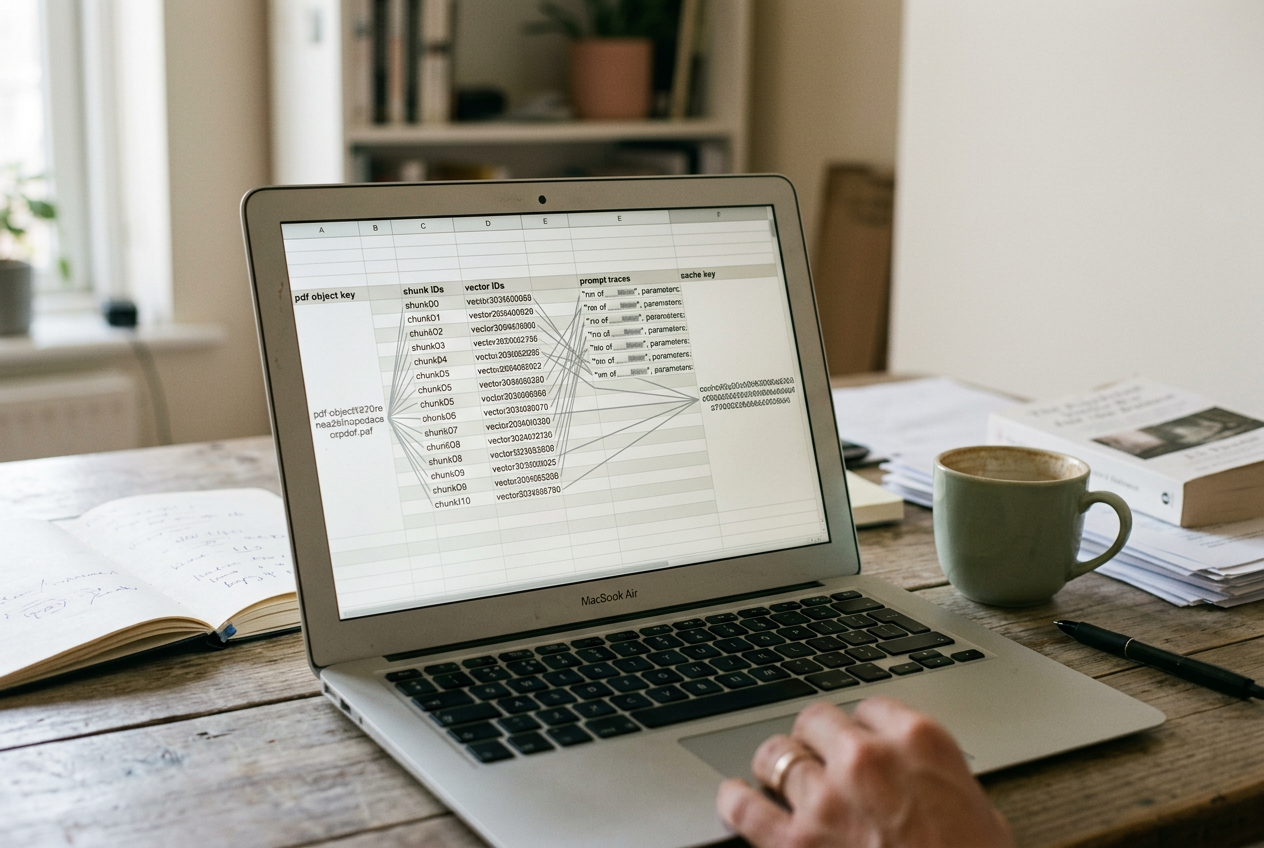
The first accountability feature is a durable acknowledgment. For the twelve-URL request, that means a unique request ID, submission time, copy of the terms in effect and a manifest showing what the service received. A manifest is an itemized machine-readable record, such as a JSON or CSV file, that another system can check without scraping an email.
The acknowledgment should preserve both the submitted URL and the provider’s normalized version. URL normalization removes variations such as tracking parameters or capitalization where appropriate, but it can also collapse distinct pages or miss the canonical address selected by a publisher. If the provider fetched a file, the record should add a cryptographic hash, a compact fingerprint used to identify matching bytes. Perceptual matching for resized or recompressed images should be reported separately because it estimates similarity rather than proving an exact match.
A message that says “we received your request” is still useful. It establishes timing and gives support staff something to locate. It does not show that the rights reservation reached a crawler, a dataset builder or a training pipeline, and the interface should not use “completed” for all four stages.
Public tools have demonstrated parts of this workflow. Spawning’s Have I Been Trained let creators search material indexed in the LAION datasets and register opt-out preferences, while Stability AI directed creators to that system during preparations for Stable Diffusion 3. The searchable index gave creators more visibility than a blank form because they could inspect candidate records. It did not create a universal deletion mechanism for every copy of a work or bind unrelated model providers.
The distinction is essential. A dataset search can show that an indexed record exists. An exclusion status can show that a participating provider marked it. Neither, by itself, proves that no duplicate entered through another URL.
Scope has to reach the training run
Return to the twelve URLs. The provider may treat them as page addresses, although the photographer intended to cover the image files displayed on those pages. It may block those exact files while retaining resized copies from a distributor. It may apply the request to the next foundation-model training run but not to fine-tuning, retrieval indexes or evaluation sets.
A verifiable system states those boundaries before submission and repeats them in the receipt. The record should identify the covered asset, the relevant dataset or data pipeline, the models governed by the request and whether the rule applies only to future collection or also to stored copies. “Future models” is too loose unless the provider defines the cutoff and explains what happens to a run already in progress.
This is where crawler controls help, but only within their stated purpose. OpenAI documents GPTBot as a web crawler that site owners can allow or disallow through robots.txt, a text file that gives automated crawlers instructions. Google offers the Google-Extended product token so publishers can manage whether crawled content helps improve certain Gemini systems without changing ordinary Google Search inclusion.
Those controls are machine-readable and independently inspectable on the publisher’s own server. They are stronger than an unrecorded preference toggle for future crawling. They do not establish that previously collected material was deleted, that copies from other domains were found or that every downstream training run consulted the rule.
OpenAI’s May 2024 announcement of Media Manager described a planned tool intended to let creators identify their works and express preferences about model training. The announcement is relevant as a proposed recognition system, not evidence that a particular work has been excluded. Product intent, an operational interface and a run-level audit record are different artifacts.
The legal requirement leaves an interface gap
The European Union’s AI Act gives general-purpose AI providers a concrete copyright duty. Article 53 requires them to put in place a policy to comply with EU copyright law and, in particular, to “identify and comply with, including through state-of-the-art technologies, a reservation of rights expressed pursuant to Article 4(3)” of the EU Copyright Directive.
A reservation of rights is the mechanism by which a rights holder withholds permission for text and data mining where the directive allows that reservation. For publicly available online content, Article 4 contemplates machine-readable means. This is related to what product teams call an opt-out, but the legal term should not be replaced casually: the reservation operates within a specific copyright framework, while a vendor’s opt-out may be broader, narrower or available worldwide as a policy choice.
The AI Act also requires providers to publish a sufficiently detailed summary of content used to train general-purpose models. Neither provision specifies a mandatory per-work dashboard, receipt schema or public API. Regulators can assess whether a provider’s policy and controls meet the law, but creators should not assume the regulation itself guarantees an asset-level confirmation screen.
That is the interface gap. The enforceable obligation concerns identifying and complying with rights reservations; the proposed accountability layer is a verifiable status record showing how a provider handled one. A form can contribute to compliance, yet the existence of a form proves little about the systems behind it.
Identity checks should prove control without collecting a dossier
Providers need safeguards against fraudulent claims. An attacker could otherwise submit requests for a competitor’s catalog, block public-domain material or use the appeal channel to learn what sits in a private dataset.
Identity verification should fit the asset. A website operator can place a token in a DNS record or at a specified path, proving control of the domain without sending a passport. A marketplace account can authenticate the seller who uploaded a work. For files distributed across third-party sites, the provider may need copyright-registration information, licensing records or a signed declaration, although collecting more personal data raises storage, security and access costs.
The twelve-URL request should therefore return a separate status for claimant verification and asset matching. “Identity verified, six assets matched, four unmatched, two disputed” is actionable. “Request denied” is not. The detailed record can remain private while exposing only a request ID and limited status through an API.
False negatives need an appeal path. A work may fail exact-hash matching because a platform recompressed it, or ownership records may use a former business name. The appeal should preserve the original request, state the reason code, accept additional evidence and identify whether human review is available. It should also record whether a training cutoff will pass while the dispute is open.
Machine-readable status turns policy into an audit trail
A workable status endpoint does not need to expose training data or model weights. Given an authenticated request ID, it could return the submitted asset identifier, provider-normalized identifier, verification state, match method, applicable systems, effective date, appeal state and last update. Each field needs a documented meaning and a version number so providers cannot quietly change what “excluded” denotes.
For the twelve-URL test, the creator should be able to export one row per asset. An exact file match might show that a stored object was placed on an exclusion list before a named training cutoff. A page that the crawler never visited could show “not collected,” which is a different and narrower claim. An unmatched image should remain unmatched rather than being presented as excluded.
The expensive part lies behind the endpoint. Providers need data lineage, meaning records that trace an item from collection through processing and use, plus versioned exclusion lists consulted by dataset jobs. Deduplication systems must propagate a valid reservation to known copies without sweeping in unrelated works. Training orchestration must freeze and record the exclusion-list version used for each run.
Retroactive removal costs more. Deleting source files does not reverse a completed training run, and machine unlearning, techniques intended to reduce a trained model’s reliance on selected data, remains difficult to validate for a particular work. A provider may decide that the reliable fallback is to exclude the work from future runs while leaving an existing model unchanged. That can be a defensible limit, but the status record must say so plainly.
Teams evaluating an opt-out system can run the twelve-URL test without access to the provider’s internal dataset. Submit controlled URLs in different formats, save the manifest, verify the identity challenge, inspect every asset’s scope and request an export after the stated cutoff. Then ask for the run identifier or audit statement showing that the applicable exclusion-list version was loaded. If the provider offers only a generic email, the test has found a support workflow, not a verifiable data-rights control.
Questions people ask
Does an opt-out receipt prove my work was removed from training data?
No. A basic receipt proves that the provider recorded a submission. Evidence of removal or exclusion requires an asset-level result, the dataset or pipeline covered, an effective cutoff and a record connecting the exclusion list to a training run. Completed models may remain unchanged even when future use stops.
Is robots.txt enough to stop AI model training?
Robots.txt can express a machine-readable instruction to crawlers that recognize the relevant token. It does not bind crawlers that ignore it, remove copies already collected or cover material obtained from another domain. Keep a dated copy of the file and check the provider’s documentation for the exact crawler and stated use.
Why does an AI provider need to verify my identity?
Verification reduces fraudulent requests and helps connect a claimant to a domain, account or work. The check should match the claim: domain control may need only a temporary token, while disputed third-party distribution may require licensing evidence. The provider should separate identity status from whether its systems found the asset.
What should
I ask an AI vendor before using its opt-out form?
Ask for a per-asset manifest, the systems and future runs covered, the meaning of each status, the treatment of duplicates and an appeal route for failed matches. Also ask whether the result can be exported through a documented machine-readable endpoint; otherwise every later audit depends on screenshots and support correspondence.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.